PikkonMG
Members
-
Joined
-
Last visited
Everything posted by PikkonMG
-
Small template update, and worth grabbing if you run a local model. I kept getting reflect timeouts when Hindsight tried to rebuild a memory page, and it turns out two of its defaults are the cause. Hindsight gives a page rebuild 300 seconds, and lets it gather up to 100,000 tokens of text before it writes anything. Fine on a hosted model. On a local one the rebuild sails past 300 seconds and gets killed, and 100,000 tokens is way past what a small model can hold, so the prompt gets cut and you end up with a worse page. Both of those are now settings on the main page, along with the Ollama window size they have to fit inside: Field Default What it does Reflect time limit 1200 Seconds a page rebuild may run before it is abandoned Reflect max context 24000 Most tokens a rebuild gathers before writing the page Ollama context size 32768 Prompt window. Keep it above Reflect max context The two reflect fields will not accept a blank. Hindsight reads them as plain numbers, and an empty value stops the container from starting, so Unraid marks them required. Ollama context size can be left blank if you are not using Ollama. Move all three together to suit your hardware. A bigger window costs more VRAM, so do not just crank it. Already running it?Here is the annoying part. Unraid will not push new fields into a container you already made, so these will not turn up on their own. You have to add them yourself. Nothing gets lost either way, since your memories sit in /mnt/user/appdata/hindsight and the container never touches them. Adding them by hand 1. Docker tab, click the Hindsight icon, choose Edit. 2. Scroll to the bottom and click Add another Path, Port, Variable, Label or Device. 3. A small window opens. Set Config Type to Variable, then fill in Name, Key and Value from one row of the table below. Leave Default Value and Display alone. 4. Click Add. The window closes and the field appears in the list. 5. Repeat steps 2 to 4 for the other rows. 6. When all three are in, click Apply at the bottom. The container restarts on its own. Name Key Value Reflect time limit HINDSIGHT_API_REFLECT_WALL_TIMEOUT 1200 Reflect max context HINDSIGHT_API_REFLECT_MAX_CONTEXT_TOKENS 24000 Ollama context size HINDSIGHT_API_LLM_OLLAMA_NUM_CTX 32768 Name is only the label you see on the Unraid page, so call it whatever you like. Key has to match exactly. If you already have Ollama context size in there, do not add a second one, just change the value to 32768. Or start fresh instead Faster if you have not changed much. Remove the container and leave the appdata folder alone when it asks. Add it back from the template, put your keys in again, and all three fields are already there. Did it work? Watch the log after it restarts. A reflect that used to die at 300 seconds should run all the way through now. Still timing out? Push Reflect time limit higher. If the pages come out thin or look like they are missing things you know are in there, your model window is probably under 32768, so bring Ollama context size and Reflect max context down to match whatever it actually is. Template and guide are in the first post.
-
Reserve.
-
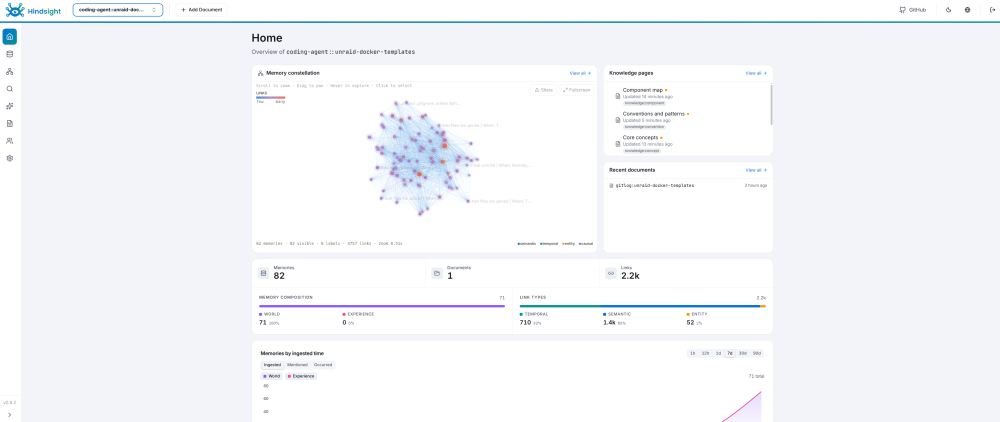
Hindsight is a memory server for AI agents. Your agents save what they work out to it and search it back later, so they stop re-deriving the same decisions every session. It speaks MCP, so anything with MCP support can talk to it: Claude Code, Cursor, Codex, Pi, Grok CLI, and the rest. I put a template together for it. It runs the official upstream image, which carries the API, the web dashboard, the search models and its own PostgreSQL, so there is nothing else to stand up alongside it. Setup guide: https://github.com/PikkonMG/unraid-docker-templates/blob/main/docs/HINDSIGHT.md Project: https://github.com/vectorize-io/hindsight Upstream docs: https://hindsight.vectorize.io Do this before you hit ApplyThe container runs as uid 1000 and will not chown its own appdata, so make the folder yourself first. On the Unraid terminal: mkdir -p /mnt/user/appdata/hindsight chown -R 1000:1000 /mnt/user/appdata/hindsight chmod 700 /mnt/user/appdata/hindsightSkip it and the container comes up, then immediately says /home/hindsight/.pg0 is not writable. Stop it, run those lines, start it again. It does not use the usual PUID and PGID variables. It needs a modelHindsight uses a language model of its own to pull facts out of whatever your agents send it. That is separate from whatever model your agents are running on, and it never talks to you directly. Point it at an Ollama box on your LAN, or paste in a key for OpenAI, Anthropic, Gemini, Groq, OpenRouter, DeepSeek or Ollama Cloud. Going the Ollama route, the model has to support tool calling or the reflect feature will not work. Use your server IP in the endpoint field, not localhost, since localhost inside the container is the container. Ports and keys8888 is the API and the MCP endpoint. 9999 is the dashboard. There are three keys. Memory API key and Web UI backend key have to hold the same value, and that is the one your agents send as a bearer token. Web UI login key is a separate one, and it is what you type to get into the dashboard. Connecting your agentsUpstream ships an installer that detects the agents you already have and wires them all up. Run it on the machine you code from, not on the server. I have only run this on Linux, so I cannot tell you how it behaves on Windows or Mac. npx @vectorize-io/hindsight-coding-agents install all \ --server self-hosted \ --api-url http://MY-UNRAID-IP:8888 \ --api-token MY-MEMORY-API-KEYThat covers Claude Code, Codex, Cursor, opencode, Pi and a few more. After it runs, each repo gets its own memory bank automatically, seeded from your commit history. Anything it does not cover is a plain MCP endpoint. One bank per project, named in the URL: http://MY-UNRAID-IP:8888/mcp/MYBANK/with an Authorization: Bearer MYTOKEN header. The guide has the config block for Cursor, Oh My Pi, plain Pi, Grok CLI and Claude Desktop, which is the one awkward case because its connector dialog has nowhere to put a bearer token. First save on a cold model takes a while, mine was about half a minute on a local one, because Ollama has to load the model before it can do anything. It settles down after that. BackupsStorage lives at /mnt/user/appdata/hindsight. The database runs inside the container but writes out to there, so it survives restarts, updates and rebuilds. Stop the container before you back that folder up. Post here if something breaks on the Unraid side and I will take a look. Bugs in Hindsight itself are better raised on their tracker: https://github.com/vectorize-io/hindsight/issues
-
Your config.yaml looks basically fine. The likely issue is the URL used in Home Assistant. For llama-swap Home Assistant should connect to the API at http://<your-unraid-ip>:8080/v1, not port 5800. The 5800 port in the logs is typically the internal llama.cpp backend launched by llama-swap. Before retrying in HA test curl http://<your-unraid-ip>:8080/v1/models from another machine. If that fails, HA will fail too.
-
Wanted to check back, did you figure it out if not please share your config.
-
That error is a YAML parse error I think, right now I can’t reproduce it from the current template working fine on my end. Please paste your current config.yaml and the full log line showing "did not find expected key" so I can check and see where it might be coming from.
-
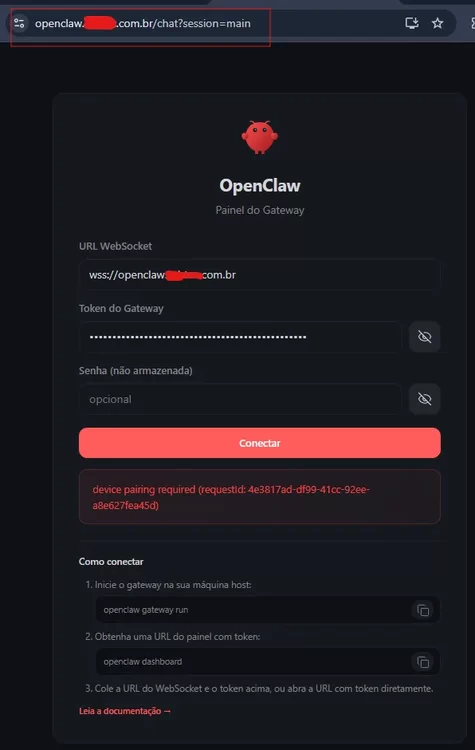
{ "gateway": { "mode": "local", "bind": "lan", "controlUi": { "allowInsecureAuth": true, "allowedOrigins": [ "http://localhost:18789", "http://127.0.0.1:18789", "http://192.168.50.250:18789" ] }, Your request id will show up from you browser like in your post on page before. Please make sure once you figure this out and get it running that you delete and reinstall it dont give out your requestid stuff like that. You can also unauthrize that id and get a new one using commandline inside the container if you wiosh to do that.
-
If your on chrome or like me edge then edge://flags/#unsafely-treat-insecure-origin-as-secure Enable Insecure origins treated as secure and add your local ip on unraid server running openclaw I.E http://192.168.1.100:18789 In your config dont use wildcard like * edit it to use the ip address of your unraid server And you have to pair you device this has been posted on a few times here now you get pairing request via the browser just take that requestid and run it with openclaw devices approve xxxxxxxx-xxxxxx-xxxxxx-4443434cac61 --token "$OPENCLAW_GATEWAY_TOKEN" inside the container.
-
Just did another test install on unraid and it installed just fine. Only difference from post on page 6 is you now get your device pairing required requestId via the browser and don't have to run openclaw devices list. Take the requestId via the browser and pair it openclaw devices approve xxxxxxxx-xxxxxx-xxxxxx-4443434cac61 --token "$OPENCLAW_GATEWAY_TOKEN" if openclaw.json is being edited while the container is running openclaw might overwrite or revert those changes. Stop the container first, edit the file, save, then restart. Also confirm /root/.openclaw is properly bind-mounted to persistent Unraid storage (/mnt/user/appdata/openclaw) or changes may be lost during container recreation.
-
I know this take will probably be unpopular with community here but most will be better off running OpenClaw or Hermes on a Raspberry Pi 5 or Budget VPS with Hetzner/Contabo/OVHCloud. Downside to VPS is local llm usage but you can get around that with wireguard/tailscale.
-
OpenClaw docker doesn't like trying to use tailscale the way unraid doesnt its container setup. Run tailscale directly on unraid.
-
This should still work https://forums.unraid.net/topic/196865-support-openclaw-ai-personal-assistant/page/6/#findComment-1614922
-
🫡 Np.
-
Template was created a few months ago and probably did what it did based off how openclaw was at the time with workarounds for Unraid permissions ects. But ya docker now should be node UID 1000. If I was an existing user id just leave it like it is as /root/.openclaw` owned by root. Switching users would cause permission errors.
-
If its related should make live soon I would think https://github.com/openclaw/openclaw/releases/tag/v2026.4.25-beta.2 "Plugins/Bonjour: stop the gateway from crash-looping on CIAO PROBING CANCELLED when the mDNS watchdog cancels a stuck probe. Restores the rejection-handler wiring dropped during the bonjour plugin migration and shares unhandled-rejection state across module instances so plugin-staged copies of openclaw/plugin-sdk/runtime register into the same handler set the host consults. Especially affects Docker on macOS, where mDNS probing reliably hits the watchdog. Thanks @troyhitch."
-
Running AMP within docker is not a supported setup. Run it in a VM or on a dedicated machine. Its been a min since I bought licence which one do you have?
-
Template for Serena MCP Server Serena is an MCP (Model Context Protocol) server that lets AI coding tools connect to your code projects. It allows MCP-compatible clients like Claude Code to access your project files, navigate code structure, and provide better context-aware responses. Setup Install via Community Applications Set your Config Directory (default: /mnt/user/appdata/serena-mcp/config/) Set your Project Directory to the folder you want Serena to access Apply and start the container First Start — Required One-Time Configuration Edit /mnt/user/appdata/serena-mcp/config/serena_config.yml and make the following changes: web_dashboard_listen_address: 0.0.0.0 gui_log_window: False web_dashboard_open_on_launch: False Restart the container after saving. Connecting Your MCP Client http://[SERVER_IP]:9121/mcp Web Dashboard: http://[SERVER_IP]:24282 Adding More Projects Click Add another Path in the Unraid template UI for each project: Field Value Host Path /mnt/user/your-project/ Container Path /workspace/your-project/ Projects on Another Machine Share the folder over SMB/NFS, mount it on Unraid via the Unassigned Devices plugin, then add it as a path: Field Value Host Path /mnt/remotes/my-pc-share/your-project/ Container Path /workspace/your-project/ Links GitHub: https://github.com/oraios/serena Docker Docs: https://github.com/oraios/serena/blob/main/DOCKER.md Template Repo: https://github.com/PikkonMG/unraid-docker-templates
-
Unraid terminal chown -R 99:100 /mnt/user/appdata/your-container If its permissions issue then chmod -R 775 /mnt/user/appdata/your-container
-
If you really want to use CubeCoders AMP on Unraid to be honest a docker container is by far the worst way to do it. It really needs its on system. If you must run it on Unraid do so within a Debian VM. Trying to run containerized game instances inside an AMP Docker container that’s the problem. You’re stacking container runtimes on top of each other. Im not saying you can't get it running just saying it's wrong way of going about doing it.
-
Not with a normal image pull alone. The container would need to be built with claude included, or have a startup script that installs it each time. Manually installing it inside the container won’t survive an update/recreate. So the proper fix is either the maintainer adding Claude Code to the image, or you making a custom image based on it. You can do something with User Script Plugin but it would be just a work around and im not even sure how to aproach it. You can also do VPS route. Create a VPS on your Unraid server and install OpenCLaw or Hermes.
-
What model you you trying to use? Try something small like phi3:mini or gemma thats 2B or lower. Check and make sure you can actually hit ollama curl http://<OLLAMA_IP>:11434/api/tags Also make sure your Ollama instance is setup to use cpu or igpu not passing NVIDIA settings like --gpus=all etc.
-
Dont use the web gui. Do openclaw onboard via the terminal in docker container. Follow the instruction set ollama and local as provider, pick you model. Use your Unraid or Ollama's IP do not use any forum of localhost or 127.0.0.1 ect example http://192.168.1.50:11434
-
I dont use tailscale so i can't say 100% I use my own wireguard server at network level. My guess based off OpenClaw Docs is that you probably need to run tailscale on unraid it's self and add your "https://your-tailnet.ts.net" along with your "10.x.x.x" to the allowedOrigins in your openclaw.json.
-
OpenClaw template already has a Variable for DISCORD_BOT_TOKEN. Just click show more settings and you will see discord, telegram , copilot ect. Start by checking that becuase if you did what you said container config now has duplicate entries for the same env var name.

-
Was no llama-swap template on CA and needed it so here we go! llama-swap is a lightweight proxy that sits in front of llama-server and allows for hot swap models. You can serve many models from a single OpenAI-compatible endpoint without manually restarting anything. Features Hot model loading and unloading Aliases and groups for multi-model concurrency OpenAI-compatible API GPU Support The template includes tags for NVIDIA (cuda), AMD (rocm), Vulkan (AMD/Intel iGPU), and CPU-only. Each tag description includes the required Extra Parameters for that GPU type. Setup config.yaml Must be manually created example config is linked to below. You can also view llama-swap github for other examples Use Unraid terminal to make edits so filesystem watchers can see files been changed for Hot Reload I.E nano /mnt/user/appdata/llama-swap/config/config.yaml "Waiting for Approval" Community Applications Install Search for llama-swap in the Apps tab Set your Models and Config directory paths Create a config.yaml in your Config directory (example config linked in the Overview) Reference your models in config.yaml as /models/yourmodel.gguf Select the tag matching your GPU and update Extra Parameters accordingly Start the container and access the UI at http://your-server-ip:8080/ui Manual Install Download the template XML from the link below Place the XML file in /boot/config/plugins/dockerMan/templates-user/ on your Unraid server In the Docker tab click Add Container and select llama-swap from the template dropdown Set your Models and Config directory paths Select the tag matching your GPU and update Extra Parameters accordingly Start the container and access the UI at http://your-server-ip:8080/ui Template download: https://raw.githubusercontent.com/PikkonMG/unraid-docker-templates/main/templates/llama-swap.xml Links GitHub: https://github.com/mostlygeek/llama-swap Example config: https://github.com/PikkonMG/unraid-docker-templates/blob/main/examples/llama-swap/example-llama-swap-config.yaml Support: https://github.com/mostlygeek/llama-swap/issues My Unraid Template Repo: https://github.com/PikkonMG/unraid-docker-templates