Rafarion
Members
-
Joined
-
Last visited
-
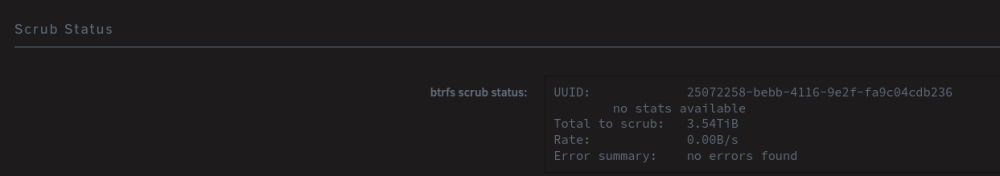
The scrubs are finished. One interesting thing is mentioned in the log on only one file and one disk device (Disk2). It also increased the corrupt count by one. Sep 9 19:09:36 Mountain kernel: BTRFS error (device md2p1): scrub: unable to fixup (regular) error at logical 2516431667200 on dev /dev/md2p1 physical 2479865724928 Sep 9 19:09:36 Mountain kernel: BTRFS warning (device md2p1): scrub: checksum error at logical 2516431667200 on dev /dev/md2p1, physical 2479865724928 root 5 inode 50073 offset 473669632 length 4096 links 1 (path: /Local/path/to/a/file) Sep 9 19:09:36 Mountain kernel: BTRFS error (device md2p1): bdev /dev/md2p1 errs: wr 0, rd 0, flush 0, corrupt 90, gen 0 UUID: 2a0d2f19-28b0-482d-9ca7-b9a36c7557a1 Scrub started: Wed Sep 9 13:42:53 2026 Status: finished Duration: 7:32:51 Total to scrub: 3.12TiB Rate: 122.19MiB/s Error summary: csum=1 Corrected: 0 Uncorrectable: 1 Unverified: 0 What I do know about this file its not touched that often, but can be on occasion. The HBA monitor on the PHY endpoints didn't report any issue, also the HBA viewer had no other report or any error. It is a disk but was introduced in the system about 1 year plus a bit more ago. So may be linked. But hard to say. I'd think I can try swapping it out, or remove the specific file that is unrecoverable? It would be something to try. I have two SMR disks in the system this is one of them. No SMR disk should be used as parity as I'm aware. But as normal operational run, could it cause these types of instabilities? Or would it look like a HBA problem, I can also just click the disk into another bay as a test. The disk 2: WDC WD60EZAZ-00ZGHB0 (Smart data also attached) (1 year and 5 month runtime) used as another disk was failing after 9 years. The disk 6: WDC WD60EZAZ-00ZGHB0 similar type (2 year and 5 month runtime) used as data extension at the time. The rest are all CMR's thoughts any thoughts on this. @MowMdown The memtest running for 3 cycles, was I believe over a few days as it takes a while run a full cycle of all test patterns. WDC_WD60EZAZ-00ZGHB0_WD-WX12D207TEVJ-20260910-1303.txt
-
Hello JorgeB. Thanks for the quick reply and input, I updated the HBA just now as per your input to latest I could find on Broadcom's site so 16.00.01.00 and also the Bios of the card is updated. I'll run the scrubs, I missed the BTRFS error counters somewhere. Its scrubbing monthly (or at least should.) but never reported any errors in the BTRFS scrub status as far as I'm aware. Its I guess its logged in the kernel log location than this one below. But If I look in the log I can indeed find the error counts, so those are these right now. So I'll keep these under observation. Sep 9 13:27:18 Mountain kernel: BTRFS info (device md1p1): bdev /dev/md1p1 errs: wr 0, rd 0, flush 0, corrupt 4, gen 0 Sep 9 13:27:21 Mountain kernel: BTRFS info (device md2p1): bdev /dev/md2p1 errs: wr 0, rd 0, flush 0, corrupt 89, gen 0 Sep 9 13:27:26 Mountain kernel: BTRFS info (device md3p1): bdev /dev/md3p1 errs: wr 0, rd 0, flush 0, corrupt 255, gen 0 Sep 9 13:27:30 Mountain kernel: BTRFS info (device md5p1): bdev /dev/md5p1 errs: wr 0, rd 0, flush 0, corrupt 5, gen 0 "but it does not rule out a PSU, power-distribution board, motherboard, or BMC-triggered reset." Agreed, I can try to see if running on one of the two supplies or checking if one can solo run the board would be informative at some point. My concern was that both supplies where running from the same battery backup and I started doubting whether it would drop or sag in voltage. Still not fully confirmed this, but I'd expect IPMI to alert on this at some level here. I didn't import any IMPI syslog as no event, nothing interesting was logged except that it re-updated the DHCP IP of its own self. Until I manually pulled the plug of one of the supplies and switched it over. BMC version is not fully the latest. Firmware Revision: 03.91, CPLD Version: 02.a1.00, Redfish Version: 1.0.1. Though I can check to update this as well. I did do an offline memtest at some point, but not to the length as maybe should i.e. ensured 1 run I recall, but maybe I only checked that all address / data lines where at least hit once with a checkerboard pattern. The last one was run on active live operating system so claimed ~100GB. But not everything. So I will revisit this perhaps. But for now lets see what it does with updated HBA firmware and addition checking on the BTRFS counters. Thanks already for the input.
-
Hello all, I'm looking for some ideas or 2nd pair of eyes to see if I can figure out an issue on my system in 2026. See below for all the details and attachments, I've tried to already figure out a lot but a bit at a loss for the moment. System is a Supermicro X10DRi Intel Dual CPU Xeon E5-2620 some details: Dual Power 1200W supply 80 Plus Titanium Dual SFP ETH card[Mellanox Technologies MT27710 Family [ConnectX-4 Lx]]: 1 in use as main to the switch Dual onboard ETH: 1 in use as bonded backup. 128 GiB DDR4 Multi-bit ECC (Depending on the run its idle: ~ 20GB, on more activity ~60GB.) 1 Zigbee USB device plugged in and available in a docker. Updated edit: SAS9300-4i controller (Temp while parity checking 65 degrees) Unraid Bootflash is on USB inside on the motherboard plugged in. (only 10% in use) IPMI/BMC available. No video card in the system, other than the mother board, so no virtualization of this component. VM's but these are pinned to CPU's IPMI is controlled by IMPI plugin from Unraid. I have a system running Unraid that is unstable mostly since start of 2026, system ran fine for pretty much entire 2025 and before. The flash written system logging doesn't show anything specifc. Sep 8 12:46:58 Mountain kernel: md: recovery thread: exit status: 0 Sep 8 12:59:12 Mountain flash_backup: adding task: /usr/local/emhttp/plugins/dynamix.my.servers/scripts/UpdateFlashBackup update Sep 8 16:30:48 Mountain webgui: Successful login user root from 10.0.0.42 Sep 8 16:59:13 Mountain flash_backup: adding task: /usr/local/emhttp/plugins/dynamix.my.servers/scripts/UpdateFlashBackup update Sep 8 17:29:13 Mountain flash_backup: adding task: /usr/local/emhttp/plugins/dynamix.my.servers/scripts/UpdateFlashBackup update Sep 8 17:40:06 Mountain monitor_nchan: Stop running nchan processes Sep 8 17:59:13 Mountain flash_backup: adding task: /usr/local/emhttp/plugins/dynamix.my.servers/scripts/UpdateFlashBackup update Sep 9 02:10:01 Mountain move: mover: started Sep 9 02:10:02 Mountain move: mover: finished (EoF Previous Syslog - Reboots Sep 9 07:23:53 timestamp -> See other boot log attached) Also see logs attached + anonymized diagnostics attached. Sometimes it runs for a month, mostly it runs for about a week, lately seems worse (but may be bias) it runs for a few days. What I have tried: Disabled dockers I started at end of 2025, seemed "a bit more stable" but I believe a bias is here. Moved several dockers also to a seperate VM to experiment. Didn't resolve anything here, these are still in this VM. No fix. Memory test run on the RAM ECC memory 3 full runs. No faults detected. Swapped out a BTRFS reporting error disk for a replacement. No fix. Tried serveral logging captures, remote and eventually on system flash usb disk. Attached is the logs of the most recent unexpected reboot, also with IPMI inpu Confirmed with IPMI no power outtage, as I get critical reports there. I even switched over one of the supplies to a seperate power phase in the house. The other is on a battery backup. I did this in August 2026. No fix. IPMI/BMC also shows no reports of any issue. I've tried to see if I can record directly from IPMI on the console, but not yet success yet in improved logging. No BBP setting enable for battery backup shutdown (Unless this is malfunctioning somehow, but don't think so) Reran another 3 days of memory test run on the RAM:No faults detected. Dove into specifics of what people observe on Xeon's (found something on power states of E3) or intel I3's. As well as the whole AMD core stating C state. I thought his would be worth an effort as well. Updated the motherboard bios to the latest from 3.2 to 3.4a. Disabled C3, C6, C1E state in bios and added kernel command line intel_idle.max_cstate=1 Added usbcore.autosuspend=-1 nvme_core.default_ps_max_latency_us=0 to kernel command line Combined of the above did not result into any change or fix. And that leaves me to pretty much to today. I've tried pcie_aspm=off and PCIE_port_pm=off but then the server did not boot with both turned settings turned on (or off). Still need to try with only one of them perhaps. What I have not tried (Yet): Removing physical RAM sticks. Removing one of the CPU's PCIe Run on different ETH controllers (SFP plug in card is running via PCIe.) Error check/validate the LSI HBA in the system. The one thing I'm trying now is additional cooling (higher fan speed) check on the LSI/HBA + PCIe as I've put the fans intially a bit lower also all 2025. (to reduce noise) But in the hottest summer ever, it was not worst than before. Delta is around 28 degrees, to 40 degrees in the room it is at. All temperatures are around 40-50 degrees of DIMMS and CPU in the IMPI. But the HBA and SFP network card are not measured does utilize a 10GB/s link. ) (Question: I think I don't have this input available, if somehow possible let me know) Moved bootflash to new medium. Turn of all dockers, don't enable the array and let it sit (reason one time it took a month to get the reboot) I've turned of less important dockers at a point, maybe it helped in longer runtime, but I think this is a bias. But this would mean a docker would lead to a full 100% cpu lockout without logging in the syslog which strikes me a bit as odd to have happen. I've tried to trace back also older changes as well, I can vaguely recall I may have done a firmware update at end of December 2025 for Unraid. But can't recall anymore which version that may have been and which version I was switching from. Question: So if all previous Unraid loaded version can be traced in a log somewhere that I'm not aware if this may be useful to see if a software version is the problem for it. My gut sense: I still think software incompatible setting of misconfiguration, but I'm also looking to check if to rip out one CPU / RAM to see what it may do. I'm mostly looking for ideas and options I've missed or just overlooked in the logs or elsewhere. The only information by ear I have is fans spin up for a bit as if temperature rises rapidly due to locked process or issue, then reboots as fans spin down and then spin up to max for the entire boot process. Thank you for reading the whole lot, any insight or help would be useful. :) Timeline of table here is the history of the instability It rebooted again 2026-09-09. So lasted a well 3 days... as of the 2026-09-06 unexpected unclean reboot + parity follows reboot Action Date Size Duration Speed Status Errors unexpected This one has an error as it rebooted during the previous parity check start... Parity-Check 2026-09-06, 02:51:44 (Sunday) 8002 GB 16 hr, 40 min, 29 sec 133,3 MB/s OK 1 unexpected Parity-Check 2026-09-05, 07:10:59 (Saturday) 8002 GB 16 hr, 40 min, 21 sec 133,3 MB/s OK 0 Parity-Check 2026-09-03, 16:39:59 (Thursday) 8002 GB 16 hr, 39 min, 58 sec 133,4 MB/s OK 0 unexpected Parity-Check 2026-08-23, 12:07:15 (Sunday) 8002 GB 23 hr, 22 min, 17 sec 95,1 MB/s OK 0 unexpected Parity-Check 2026-08-21, 05:01:10 (Friday) 8002 GB 17 hr, 8 min, 34 sec 129,7 MB/s OK 0 unexpected Parity-Check 2026-08-19, 11:00:04 (Wednesday) 8002 GB 16 hr, 52 min, 36 sec 131,7 MB/s OK 0 Parity-Check 2026-08-06, 16:39:58 (Thursday) 8002 GB 16 hr, 39 min, 56 sec 133,4 MB/s OK 0 Parity-Check 2026-07-02, 16:41:13 (Thursday) 8002 GB 16 hr, 41 min, 12 sec 133,2 MB/s OK 0 unexpected Parity-Check 2026-06-20, 07:36:01 (Saturday) 8002 GB 16 hr, 39 min, 22 sec 133,4 MB/s OK 0 unexpected Parity-Check 2026-06-17, 17:07:36 (Wednesday) 8002 GB 21 hr, 1 min, 57 sec 105,7 MB/s OK 0 A disk had BTRFS errors. So swapped disk to larger Data-Rebuild 2026-06-12, 09:12:49 (Friday) 6001 GB 13 hr, 29 min, 25 sec 123,6 MB/s OK 0 unexpected I believe I had it fixed with Dockers disabled for some at this stage, but no avail. Parity-Check 2026-06-10, 22:08:03 (Wednesday) 8002 GB 18 hr, 26 min, 32 sec 120,5 MB/s OK 0 Parity-Check 2026-06-04, 18:27:04 (Thursday) 8002 GB 18 hr, 27 min, 3 sec 120,5 MB/s OK 0 Parity-Check 2026-05-28, 08:53:24 (Thursday) 8002 GB 18 hr, 29 min, 45 sec 120,2 MB/s OK 0 unexpected Parity-Check 2026-05-09, 10:42:49 (Saturday) 8002 GB 18 hr, 25 min, 41 sec 120,6 MB/s OK 0 Parity-Check 2026-05-07, 16:29:46 (Thursday) 8002 GB 18 hr, 29 min, 45 sec 120,2 MB/s OK 0 unexpected Parity-Check 2026-04-29, 19:33:12 (Wednesday) 8002 GB 18 hr, 27 min, 31 sec 120,4 MB/s OK 0 Parity-Check 2026-04-02, 16:24:50 (Thursday) 8002 GB 18 hr, 24 min, 49 sec 120,7 MB/s OK 0 unexpected Parity-Check 2026-03-28, 00:16:59 (Saturday) 8002 GB 18 hr, 26 min, 38 sec 120,5 MB/s OK 0 unexpected Parity-Check 2026-03-23, 05:30:25 (Monday) 8002 GB 23 hr, 26 min, 29 sec 94,8 MB/s OK 0 Parity-Check 2026-03-05, 16:24:07 (Thursday) 8002 GB 18 hr, 24 min, 6 sec 120,8 MB/s OK 0 unexpected Parity-Check 2026-02-13, 11:13:18 (Friday) 8002 GB 18 hr, 44 min, 7 sec 118,6 MB/s OK 0 Parity-Check 2026-02-05, 17:27:37 (Thursday) 8002 GB 19 hr, 27 min, 36 sec 114,2 MB/s OK 0 unexpected Parity-Check 2026-01-27, 00:24:02 (Tuesday) 8002 GB 18 hr, 25 min, 32 sec 120,6 MB/s OK 0 Parity-Check 2026-01-08, 16:23:23 (Thursday) 8002 GB 18 hr, 23 min, 22 sec 120,9 MB/s OK 0 2026^ Parity-Check 2025-12-04, 16:24:19 (Thursday) 8002 GB 18 hr, 24 min, 18 sec 120,8 MB/s OK 0 Parity-Check 2025-11-06, 16:22:17 (Thursday) 8002 GB 18 hr, 22 min, 16 sec 121,0 MB/s OK 0 Parity-Check 2025-10-02, 16:22:36 (Thursday) 8002 GB 18 hr, 22 min, 35 sec 121,0 MB/s OK 0 Disk replacement 9 year old runtime Data-Rebuild 2025-09-07, 05:01:41 (Sunday) 4001 GB 9 hr, 54 min, 54 sec 112,1 MB/s OK 0 Parity-Check 2025-09-04, 16:28:41 (Thursday) 8002 GB 18 hr, 28 min, 40 sec 120,3 MB/s OK 0 Can't recall, suspicious? Parity-Check 2025-09-01, 17:15:20 (Monday) 8002 GB 18 hr, 28 min, 36 sec 120,3 MB/s OK 0 Parity-Check 2025-08-07, 16:29:01 (Thursday) 8002 GB 18 hr, 29 min 120,3 MB/s OK 0 Disk addition Disk-Clear 2025-07-15, 22:09:07 (Tuesday) 6001 GB 11 hr, 54 min, 43 sec 139,9 MB/s OK 0 Parity-Check 2025-07-03, 16:25:09 (Thursday) 8002 GB 18 hr, 25 min, 8 sec 120,7 MB/s OK 0 Parity-Check 2025-06-05, 16:25:17 (Thursday) 8002 GB 18 hr, 25 min, 15 sec 120,7 MB/s OK 0 Parity-Check 2025-05-08, 16:24:42 (Thursday) 8002 GB 18 hr, 24 min, 41 sec 120,7 MB/s OK 0 Parity-Check 2025-04-03, 16:24:48 (Thursday) 8002 GB 18 hr, 24 min, 47 sec 120,7 MB/s OK 0 Parity-Check 2025-03-06, 18:17:32 (Thursday) 8002 GB 20 hr, 17 min, 31 sec 109,5 MB/s OK 0 Parity-Check 2025-02-06, 16:25:36 (Thursday) 8002 GB 18 hr, 25 min, 35 sec 120,6 MB/s OK mountain-diagnostics-20260909-0943.zip Sep 9 kernel Log Previous Sep 7 kernel log to Sep 9
-
Just to update this item, in case some one in the future would stumble across this. At the moment I replaced the Crucial disk for a different branded (WD blue SSD 1TB). Based on the supply remark from JorgeB (Thanks, was a good thing to change as well) I also switched it to another supply rail in the supply. Now the waiting game starts for another 1 to 1.5 weeks to see if it shows up again. And as I'm mostly wanting to ensure an operational server instead of bug-hunting the exact cause. I can't be sure if its a mix of the crucial with this specific configuration or if it was a potential bad supply rail or connector of the Sata if it is resolved now. This means that in the even I'd probably don't reply here within another 2-3 weeks, the issue is probably resolved.
-
I'm looking for some secondary support for an issue I've tried to solve for a few weeks as it takes some time to occur. Some history: The server was running a cache setup with 2 SSD's of 240GB on BTRFS RAID1. About 2 months ago I upgraded my cache to two new disks to have more cache space: 2x 1TB (CT1000MX500SSD1). As far as I'm aware I properly swapped these one by one to preserve the mirrored cached data. It seems I'm losing a disk after about 1 or 1.5 week with the following errors: Jan 24 02:07:53 Mountain kernel: ata1.00: exception Emask 0x0 SAct 0xffffffff SErr 0x0 action 0x6 frozen Jan 24 02:07:53 Mountain kernel: ata1.00: failed command: WRITE FPDMA QUEUED Jan 24 02:07:53 Mountain kernel: ata1.00: cmd 61/20:00:30:b4:3a/00:00:08:00:00/40 tag 0 ncq dma 16384 out Jan 24 02:07:53 Mountain kernel: res 40/00:01:01:4f:c2/00:00:00:00:00/00 Emask 0x4 (timeout) [...] Jan 24 02:07:53 Mountain kernel: ata1.00: status: { DRDY } Jan 24 02:07:53 Mountain kernel: ata1: hard resetting link Jan 24 02:07:59 Mountain kernel: ata1: found unknown device (class 0) Jan 24 02:08:03 Mountain kernel: ata1: softreset failed (device not ready) Jan 24 02:08:03 Mountain kernel: ata1: hard resetting link Jan 24 02:08:09 Mountain kernel: ata1: found unknown device (class 0) Jan 24 02:08:13 Mountain kernel: ata1: softreset failed (device not ready) Jan 24 02:08:13 Mountain kernel: ata1: hard resetting link Jan 24 02:08:19 Mountain kernel: ata1: found unknown device (class 0) Jan 24 02:08:24 Mountain kernel: ata1: link is slow to respond, please be patient (ready=0) Jan 24 02:08:48 Mountain kernel: ata1: softreset failed (device not ready) Jan 24 02:08:48 Mountain kernel: ata1: limiting SATA link speed to 3.0 Gbps Jan 24 02:08:48 Mountain kernel: ata1: hard resetting link Jan 24 02:08:53 Mountain kernel: ata1: found unknown device (class 0) Jan 24 02:08:54 Mountain kernel: ata1: softreset failed (device not ready) Jan 24 02:08:54 Mountain kernel: ata1: reset failed, giving up Jan 24 02:08:54 Mountain kernel: ata1.00: disable device Jan 24 02:08:54 Mountain kernel: ata1: EH complete Jan 24 02:08:54 Mountain kernel: sd 2:0:0:0: [sdc] tag#12 UNKNOWN(0x2003) Result: hostbyte=0x04 driverbyte=DRIVER_OK cmd_age=0s Jan 24 02:08:54 Mountain kernel: sd 2:0:0:0: [sdc] tag#20 UNKNOWN(0x2003) Result: hostbyte=0x04 driverbyte=DRIVER_OK cmd_age=0s Jan 24 02:08:54 Mountain kernel: sd 2:0:0:0: [sdc] tag#12 CDB: opcode=0x2a 2a 00 08 38 76 98 00 00 40 00 Jan 24 02:08:54 Mountain kernel: sd 2:0:0:0: [sdc] tag#20 CDB: opcode=0x28 28 00 0b 13 24 e0 00 00 20 00 Initial the logs seemed unclear on which exact disk it was so I tried the following in sequence. Configuration 2x 1TB (CT1000MX500SSD1). - Switched SATA ports on motherboard to different ports. - Switched SATA Cables to new cables. Marked specific disk which causing the issue: - Switched power SATA between reported error disk - Switched out specific SATA Cable of the reported error disk and switched a port. ----------------------------------------------------------------------------------------------------------------------------------------------------- Believed single disk failure removed error disk and changed hardware configuration Configuration: 2x 1TB (CT1000MX500SSD1 and Samsung_SSD_870_EVO_1TB) - Error occurred again on this time the other: CT1000MX500SSD1 (SDC) So i'm out most logical ideas, should I also swap out this CT1000MX or I'd reckon its something else. Now I'm thinking the following: I had two bad disks, but seems very unlikely? Motherboard is having issues, or specifically with this type of disk? A software misconfiguration that can cause this disk access issue? I'm hoping someone can help or at least maybe have a few other options to attempt. Attached is the diagnostics in case any more specific information is needed. (syslog1, probably most useful). mountain-diagnostics-20230124-1848.zip