





Nedio Server Unraid
Members
-
Joined
-
Last visited
-
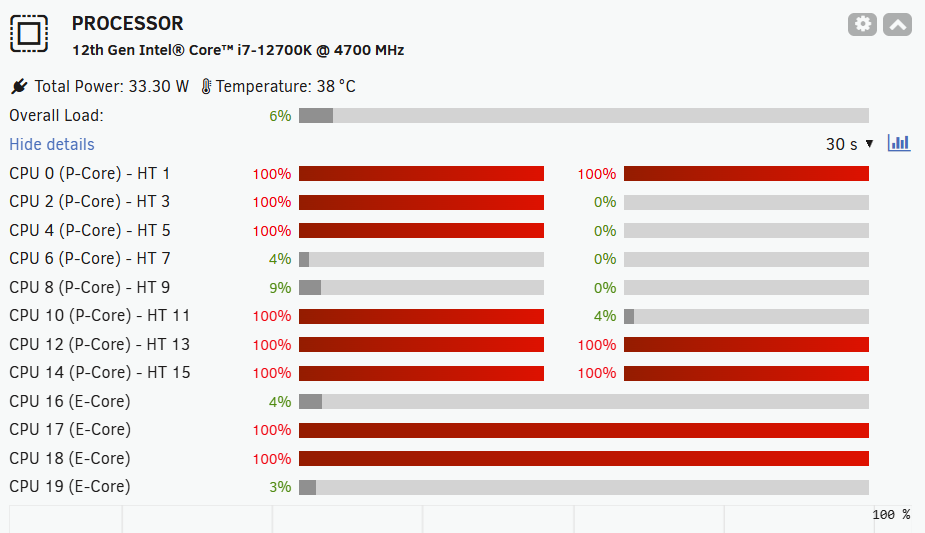
Hi, Since some months now, I noticed that any process can use all available CPUs. For example updating my docker containers has become complicated and often fails to remove the container before starting it with the new image. Also my immich docker (installed via CA) was using all the CPU when files are synced to it (for transcoding and other ML activities), rendering my server unavailable/inaccessible until the CPUs are freed. Now I moved my immich installation to docker compose with a dedicated container for ML, so that I can control the resources it is allowed to use. But the issue with docker updates is still there. I see this: And UI does not refresh anymore. I can't ssh into the box. Nothing responds. Please advise on few fronts: 1) How can I make sure that my unraid server OS always has 2 CPU cores reserved for itself (and nothing can steal those). 2) How can I get the docker updates working seamlessly? They often fail, leave the orphan containers, case my docker container disappear from the list (leaving me with the only option to reinstall those from previous apps) etc. nedio-server-diagnostics-20261104-1421.zip
-
All the scrubs run ok, no errors. VMs started. I'd say the topic closed. Thank you @JorgeB!
-
nedio-server-diagnostics-20261104-1154.zip
-
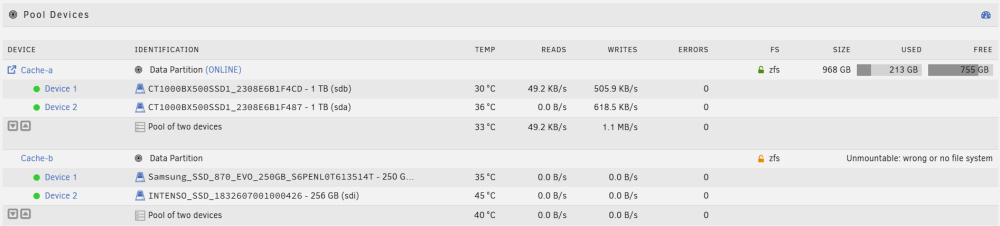
did that. array started. looks good on the Main. phew. before starting to format the cache-b, how should I verify that cache-a is in-tact now?
-
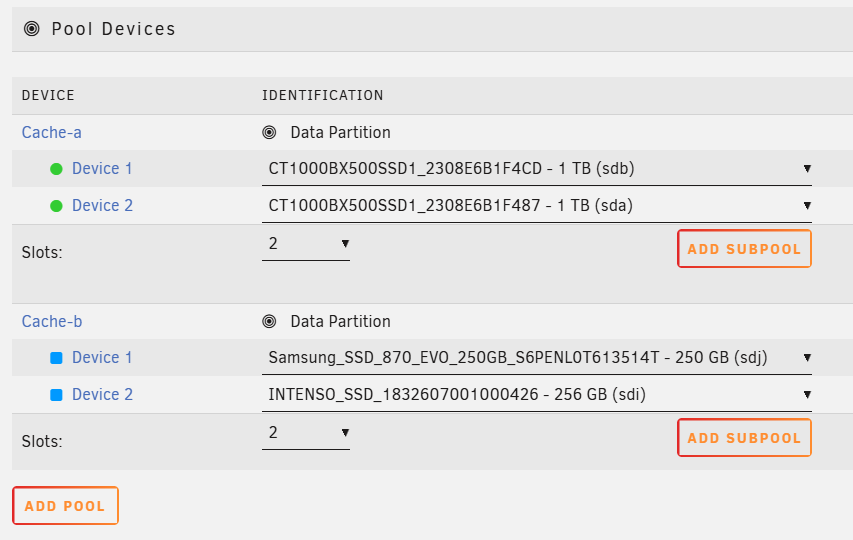
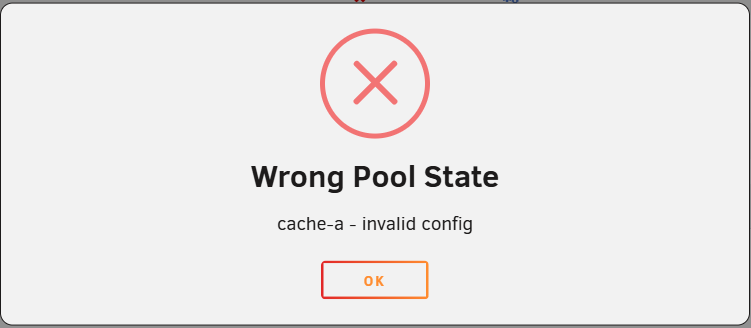
I followed your suggested steps all the way to #4. But now I can't start the array. What do I do now? nedio-server-diagnostics-20261104-1008.zip
-
Thank you @JorgeB ! I will follow the steps you advised tonight. The 840 EVO is not detected as I have disconnected it and connected the replacement disk already.
-
Hi, My zfs cache pool with 2 slots has degraded. Not sure what's the root cause. But need the array back, so I guess will have to rebuild the pool. Since one of the two SSD disks is old and far beyond the write limits, I decided to not rebuild the pool mirror onto it and got a replacement. My cache-b shows 1 vdev with 3 devices. I never had 3 devices on this pool. (diag attached). So the pool config got corrupted? My idea now is to: 1) Remove the pool 2) Re-create a 2 slot zfs pool with same name (cache-b) and props 3) Assign the good disk to slot 1, none to slot 2 and Start Array 4) Optional: copy the data of the pool into array (backup). 5) Stop the array and assign new disk (pre-cleared) to the 2nd slot 6) Start array so that the zfs pool is rebuild Is this plan correct? (double checking here, don't want to lose data). nedio-server-diagnostics-20261028-0823.zip
-
issue resolved - it was the slow network (going via power line). replaced that with LAN - all good now. 🙈
-
Hi, I am running immich 2.x on my unraid v7.1.4. The UI of Unraid as well as writing to the cache pools (ZFS) are ultra slow (2-7MB/s). Please advise where to start troubleshooting.. This was working well before, and is unbearable now. Immich backup uploads assets in the range of KB/s, hangs. Attaching the diagnostics. Thanks nedio-server-diagnostics-20251009-1551.zip
-
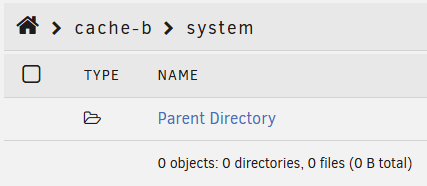
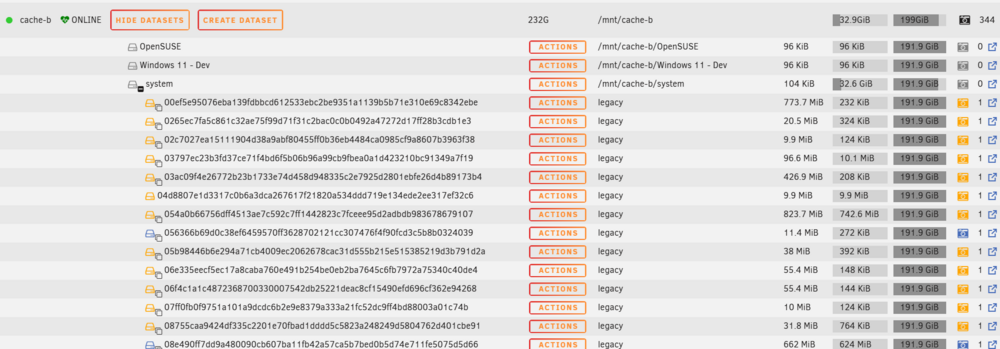
ok, my disk 2 was rebuilt. no errors so far 🤞. Now I want to eliminate the potential reason of the cache-b holding back from array stop/clean reboot.. I have changed the docker settings to be overlay2. Did not enable docker yet. Also I have moved everything from cache-b to array (using the mover). Now, since there is nothing on the cache-b, I would expect to see 0 on the sizes in Main tab: But I see some misterious 35 GB on it. Then I noticed that there are 344 snapshots (legacy) of the system share folder in the cache-b pool. (those grey/yellow/blue photo camera icons are confusing 😕) I want to clean the cache-b. Can I just delete these snapshots? I need to get rid of those legacy snapshots and stop them being taken.
-
Thank you @JorgeB! I think the answers to both parts of the condition you mentioned are "Yes". But just to clarify, how/where do I see if the emulated disk 2 is mounting? It shows as disabled in the array with a ❌ mark.
-
Ok, hard restarted 🥶, started the array in maintenance mode (docker and VM are still off). Did the XFS check on disk 2 - no errors detected 🥳 Phase 1 - find and verify superblock... Phase 2 - using internal log - zero log... - scan filesystem freespace and inode maps... - found root inode chunk Phase 3 - for each AG... - scan (but don't clear) agi unlinked lists... - process known inodes and perform inode discovery... - agno = 0 - agno = 1 - agno = 2 - agno = 3 - process newly discovered inodes... Phase 4 - check for duplicate blocks... - setting up duplicate extent list... - check for inodes claiming duplicate blocks... - agno = 0 - agno = 1 - agno = 2 - agno = 3 No modify flag set, skipping phase 5 Phase 6 - check inode connectivity... - traversing filesystem ... - traversal finished ... - moving disconnected inodes to lost+found ... Phase 7 - verify link counts... No modify flag set, skipping filesystem flush and exiting. No file system corruption detected. The disc 2 still shows disabled. What are the next steps? I can't find the rebuilding-a-drive-onto-itself in the unraid documentation.. Did the procedure of restoring the disabled disc change? How should I proceed to fix the array?
-
I had switched to docker folder as my docker image file would get corrupt several times (due to not being able to shutdown the system cleanly and having to hard restart).. I will look into re-creating it using overlay2 driver, thanks! For now - any idea how do I proceed? Is it that the only option I have a hard restart again? Since my array is not ok, do I risk to get in trouble even more if I hard restart?
-
Here's the outcome: SRV:~# lsof | grep /mnt SRV:~# ps -f | grep "bash" | grep -v "grep" root 3081899 3081748 0 23:54 pts/0 00:00:00 /bin/bash --login SRV:~#
-
Yeah, docker was already stopped at the time of the diags taking (from the settings > docker > enable docker=No). The web-console was also closed (after diag extract). Still I have run the command you suggested. SRV:~# /etc/rc.d/rc.docker status Docker daemon is not running. SRV:~# /etc/rc.d/rc.docker stop rc.docker: Stopping containers... rc.docker: Stopping network... rc.docker: Stopping Docker daemon... rc.docker: Docker daemon... Already stopped. SRV:~# tail -f /var/log/syslog Sep 20 21:22:35 nedio-server emhttpd: Unmounting disks... Sep 20 21:22:35 nedio-server emhttpd: shcmd (39782356): /usr/sbin/zpool export -f cache-b Sep 20 21:22:36 nedio-server root: cannot export 'cache-b': pool is busy Sep 20 21:22:36 nedio-server emhttpd: shcmd (39782356): exit status: 1 Sep 20 21:22:36 nedio-server emhttpd: Retry unmounting disk share(s)... Sep 20 21:22:41 nedio-server emhttpd: Unmounting disks... Sep 20 21:22:41 nedio-server emhttpd: shcmd (39782357): /usr/sbin/zpool export -f cache-b Sep 20 21:22:41 nedio-server root: cannot export 'cache-b': pool is busy Sep 20 21:22:41 nedio-server emhttpd: shcmd (39782357): exit status: 1 Sep 20 21:22:41 nedio-server emhttpd: Retry unmounting disk share(s)... SRV:~#Isn't there a way to figure out what could be hugging the pool cache-b ?


