





raqisasim
Members
-
Joined
-
Hi all -- I just wanted to add how I recommend to configure the Repository Server function, as the official instructions assume some things that are not in-play with Docker/UnRAID. If you've followed these instructions above to get started, they certain worked for me! But I wanted to backup machines in my LAN, not just my UnRAID folders. To do that, it seems, you need to use different configurations to make this work. And -- I'm not certain this'll work with an existing setup. It appears the local repo you create holds some of this cert info. I ended up wiping my appdata and repo (it was brand new) to make the below work. So: Open up your container template, and ensure you're on Advanced View. Then, go ahead and create a new Variable, KOPIA_SERVER_CONTROL_PASSWORD, and provide that value. Next, create a Path, call it Certs, with the Container Path of /certs and the Host Path being a /certs sub-folder under wherever you store you Kopia AppData. Then, update your Post Arguments to now read as follows (note this is a one-time run): server start --tls-generate-cert --tls-cert-file /certs/my.cert --tls-key-file /certs/my.key --address 0.0.0.0:51515 --server-control-username control --server-username=<USERNAME_FOR_SERVER> --server-password=<PASSWORD_FOR_SERVER> Then re-start the container and open up the logs. If the above is successful, the logs will contain the critical SERVER CERT that you need to store like a password: SERVER CERT SHA256: <SERVER_CERT_TO_TREAT_LIKE_PASSWORD-STORE_IT_NOW> writing TLS certificate to /certs/my.cert writing TLS private key to /certs/my.key SERVER ADDRESS: https://[::]:51515 Open the address above in a web browser to use the UI. (Caution! Do not re-start this container until you do the next section to avoid errors upon start!) Note that your URL to access the UI also changes! You're now on https, not http, same host and port. You'll know you're on right URL if it throws warnings about "Your connection is not private" (on Chrome-based browsers) or "Warning: Potential Security Risk Ahead" (Firefox-based ones). So test and confirm you can login with your USERNAME_FOR_SERVER and PASSWORD_FOR_SERVER. If good, double-check you've stored securely the SERVER_CERT_TO_TREAT_LIKE_PASSWORD-STORE_IT_NOW value, please. Now let's remove the part that will cause start failures if you restart the container. Close that login window (this avoids annoying CRSF errors in log) and go back to your container template. Edit it to remove the "--tls-generate-cert" command: server start --tls-cert-file /certs/my.cert --tls-key-file /certs/my.key --address 0.0.0.0:51515 --server-control-username control --server-username=<USERNAME_FOR_SERVER> --server-password=<PASSWORD_FOR_SERVER>Hit apply and let the container restart. Now, you'll pass that SERVER_CERT_TO_TREAT_LIKE_PASSWORD-STORE_IT_NOW value when your Kopia client connects to your Repository Server, and it should work a charm. Good luck!
-
Yes -- the weirdness per my last post was that Fix Common Problems said it was Disabled, but it wasn't. Sorry for the delay getting back; we've had a few other things 'round the house impacting my time to debug this. So what appears to have happened, was something around the Mover not actually moving anything. There was an additional script to help QBittorrent work with the Mover that actually had stopped working, but wasn't throwing any visible errors. End result is that I killed that script, and then re-ran Mover and now it's moving, plus Fix Common Problems says everything is OK with the cache, now. So I'm going to tentatively blame this all on this, and remember to keep an eye on fancy helper scripts going forward!
-
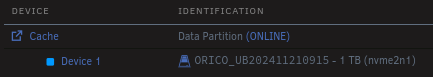
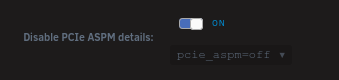
Update -- another cache disable, different SSD(?!?!) -- first, thank you all for the advice and help! But here's the new weirdness (new diags, attached). Per my original post, I did as I had before when this 1st occurred: I cleaned off and used a differed SSD, already in my system, for cache. Then, overnight (again!) -- Fix Common Problems ran at 4:40AM and 7:50AM ET (this a manual run), and both times reported my new cache drive was disabled: Sep 10 07:50:12 Morningstar root: Fix Common Problems: Error: cache (ORICO_UB202411210915) is disabled But! Then I went and looked, and the cache appear normal: So that's even more weird, right? This is a totally different SSD, not even the same manufacturer, and one that's been mounted and in-use on and off as a "scratch pad" for almost a year, now, as well as the prior cache until I re-installed per 1st post. I do also notice none of my drives are spinning down: Sep 10 08:11:07 Morningstar root: Total Spundown: 0 Also: MowMdown's pcie_aspm=off is already implemented in my system, and has been since before this fancy new interface: And I am running CPU in Best Performance mode. I get it being a false alarm save that the Samsung one really did go disabled on me, so something happened, there. For now, I'll disable Mover as a starting point, run Mover manually when I can this evening and check things right after. Other ideas, or things I've missed, are welcome! morningstar-diagnostics-20260910-0807.zip
-
A few weeks ago, my Samsung SSD cache disabled. I moved an already-mounted SSD to act as cache, and pulled this one. Testing found no issues, so I planned to reformat/restore it, thinking it was a transient issue. I did that yesterday, and overnight it was disabled again. Specifically, per syslog: As of 4AM ET, mover ran and no errors reported As of 4:40AM ET, Fix Common Problems ran and reported "Error: cache (Samsung_SSD_990_PRO_2TB_S7KHNJ0X312749R) is disabled" I've run the full SMART test and attached it here, along with the diags from before that full test. That came up clean, as well. The only other thing I could find is below, in my dmesg: [66672.535303] XFS (nvme0n1p1): Mounting V5 Filesystem 00ecfc48-3876-4328-95b5-1615bfbef65e [66672.541689] XFS (nvme0n1p1): Ending clean mount [152151.312270] block nvme0n1: the capability attribute has been deprecated.Ideas on what I'm missing here, welcome. Thank you. morningstar-smart-20260909-0626(1).zip morningstar-diagnostics-20260909-0630.zip
-
Thanks again -- for anyone else running into this situation, I did an Extended SMART which came up clean as well, pushed some cables, and am currently doing a data rebuild based on official guidance: https://docs.unraid.net/unraid-os/using-unraid-to/manage-storage/array/replacing-disks-in-array/#re-enabling-a-disabled-disk-rebuilding-onto-itself
-
Hi all -- wanted to confirm with my logs/situation what I gathered from this post, that a high Correction algorithm invocations count is not necessarily indicative of a bad drive, per the below: Error counter log: Errors Corrected by Total Correction Gigabytes Total ECC rereads/ errors algorithm processed uncorrected fast | delayed rewrites corrected invocations [10^9 bytes] errors read: 0 0 0 0 9823616 368586.466 0 write: 0 0 0 0 6846490 95087.111 0 verify: 0 0 0 0 247462 0.000 0 That said, I do see this in my syslog from yesterday, when UnRAID kicked the drive offline: Apr 20 11:11:43 Morningstar kernel: mpt3sas_cm0: log_info(0x31120436): originator(PL), code(0x12), sub_code(0x0436) Apr 20 11:11:43 Morningstar kernel: mpt3sas_cm0: log_info(0x31120303): originator(PL), code(0x12), sub_code(0x0303) ### [PREVIOUS LINE REPEATED 48 TIMES] ### Apr 20 11:14:17 Morningstar kernel: sd 10:0:6:0: [sdm] tag#1529 UNKNOWN(0x2003) Result: hostbyte=0x0b driverbyte=DRIVER_OK cmd_age=0s Apr 20 11:14:17 Morningstar kernel: sd 10:0:6:0: [sdm] tag#1529 CDB: opcode=0x2a 2a 00 60 2e c2 bb 00 00 80 00 Apr 20 11:14:17 Morningstar kernel: I/O error, dev sdm, sector 12909417944 op 0x1:(WRITE) flags 0x0 phys_seg 128 prio class 0 Apr 20 11:14:17 Morningstar kernel: md: disk11 write error, sector=12909417880 The disk11 write error repeats about 30 times before the drive goes offline. So the question is, is this a weird one-off, or a sign of trouble to come? I did try to run a Long Self-Test, and it Aborted, but I also see there can be many reasons for that, as well. Diags attached, and thanks for any help and advice! morningstar-diagnostics-20260421-2241.zip morningstar-smart-20260421-2240.zip
-
Follow-ups: I forgot to mention that post-Docker.img re-creation, that I did lose all the Docker networks for the VPNs I had. I did my final tests before posting yesterday against a re-created VPN. What has also happened, is that now even containers I created after that with VNC connections, such as FirefoxESR, won't connect to VNC if I'm on the VPN. This is not the prior behavior, nor the behavior I recall from my tests yesterday. It works fine when connected to the bridge network. My gut -- for what little that's worth -- says there's something deeply broken about my docker networking stack. For reference, post-docker.img re-creation: docker network ls NETWORK ID NAME DRIVER SCOPE e0d4cdd9fc47 bridge bridge local 6ab26766bcf9 host host local 19bb0f77fd87 none null local 5832de116521 wg6 bridge localwg0 thru 5 are tunnels created prior to the docker.img deletion, two of which I created yesterday in my earlier testing. Ideas welcome, as I'm pretty stumped.
-
UnRaid 7.2.3. I noticed today that Dockers setup to run thru VPNs setup via VPN Manager are no longer reaching the Internet. this includes both full restart, and deletion of docker.img file and recreation of key containers to test against. Below is a segment of my syslog when I start and stop one such Docker that is aligned to a VPN that has worked before (as of yesterday, to be exact): Dec 28 18:42:54 Morningstar kernel: br-f1c71bf35e99: port 1(vethb1fca43) entered disabled state Dec 28 18:42:54 Morningstar kernel: vethaa67c28: renamed from eth0 Dec 28 18:42:54 Morningstar kernel: br-f1c71bf35e99: port 1(vethb1fca43) entered disabled state Dec 28 18:42:54 Morningstar kernel: vethb1fca43 (unregistering): left allmulticast mode Dec 28 18:42:54 Morningstar kernel: vethb1fca43 (unregistering): left promiscuous mode Dec 28 18:42:54 Morningstar kernel: br-f1c71bf35e99: port 1(vethb1fca43) entered disabled state Dec 28 18:42:54 Morningstar kernel: br-f1c71bf35e99: port 1(vethb1fca43) entered disabled state Dec 28 18:42:54 Morningstar kernel: vethaa67c28: renamed from eth0 Dec 28 18:42:54 Morningstar kernel: br-f1c71bf35e99: port 1(vethb1fca43) entered disabled state Dec 28 18:42:54 Morningstar kernel: vethb1fca43 (unregistering): left allmulticast mode Dec 28 18:42:54 Morningstar kernel: vethb1fca43 (unregistering): left promiscuous mode Dec 28 18:42:54 Morningstar kernel: br-f1c71bf35e99: port 1(vethb1fca43) entered disabled stateA sample of a few Dockers, both on VPNs and on Bridge, shows I get similar messages as above when I start and stop them; only the "vethb1fca43" changes. I will also note that, when I switch Dockers to Bridge, they can reach the Internet (tested by switching my Firefox ESR Docker from VPN to Bridge. I can find few references to this issue, elsewhere. A couple other notes: Saw reference to needing ipv6 enabled; not sure why I'd need that now as I've had it disabled in both UnRaid and OPNSense for some time. Was up to 87% full with Docker Image file; I did re-create it with more space, and you can see in logs I got, for a time post-resizing, a error saying Docker image file couldn't mount. Eventually, it did. I did update OPNSense to 25.7.10 yesterday; however, everything worked fine after that, up until today. Thanks for the help! morningstar-diagnostics-20251228-2003.zip
-
For future reference for others, everything has now run overnight successfully. I did get new disks, but I also looked at my mess of a cabling solution and brought in new SATA data and power connectors, and rewired/documented everything, double-checking connectors and the like. I did have distressingly loose SATA data cable connectors, despite the locking mechanism, so it's possible that was the proximate culprit. The 2 new drives have synced without errors reported, and the system is working as per normal. Thanks again!
-
The UPS it's attached to did just shutdown, out of the blue, a couple weeks ago. Maybe I should try swapping in other UPS + using my Power Supply tester, plus double-checking connectors? I should have a spare power supply around here as well.
-
On Unraid 7.2.2 with 2 Parity Drives -- and 2 drives offline due to errors, over the course of 2 days. Because I lost a drive yesterday, and now today, I looked again in the logs, and raise this ask for help. I see this error in the logs among the more standard "kernel: md: diskxx read error" errors: Nov 30 18:29:01 Morningstar kernel: pcieport 0000:00:01.1: AER: Correctable error message received from 0000:00:01.1 Nov 30 18:29:01 Morningstar kernel: pcieport 0000:00:01.1: PCIe Bus Error: severity=Correctable, type=Physical Layer, (Receiver ID) Nov 30 18:29:01 Morningstar kernel: pcieport 0000:00:01.1: device [8086:462d] error status/mask=00000001/00002000 As well as this: kernel: ata6.00: exception Emask 0x10 SAct 0x400 SErr 0x4090000 action 0xe frozen Thus my concern of a broader issue, as [8086:462d] is a PCI Bridge: 00:01.1 PCI bridge: Intel Corporation Device 462d (rev 05) I wonder, for example, if my LSI 9305-16I is failing and taking drives down with it, but I lack experience in interpreting this information. Any advice on how to troubleshoot, or what my root cause is, is welcome. FYI, I moved to 7.2.2 just under 10 days ago. Thank you! morningstar-diagnostics-20251204-1214.zip
-
Hi. So I just ran into this issue, as well, and this command resolved it: ln -s /var/local/emhttp /usr/local/emhttp/stateThe commonality appears to be not just UnBalance, but bulk file movements in general. I was copying about 100G/4K files thru an SMB mount from my desktop to my UnRAID when this occurred. A similar copy didn't trigger it earlier, I think; for reference this was copying to a Share that has a 2TB cache --> Array setup. I'm attaching my diags, but also the contents of /var/log/phplog, given it's actually showing some kind of errors, as others have reported: [14-Nov-2025 20:27:52 America/New_York] PHP Fatal error: Uncaught TypeError: extract(): Argument #1 ($array) must be of type array, false given in /usr/local/emhttp/plugins/dynamix/template. php:50 Stack trace: #0 /usr/local/emhttp/plugins/dynamix/template.php(50): extract(false) #1 {main} thrown in /usr/local/emhttp/plugins/dynamix/template.php on line 50 [14-Nov-2025 20:27:55 America/New_York] PHP Fatal error: Uncaught TypeError: extract(): Argument #1 ($array) must be of type array, false given in /usr/local/emhttp/plugins/dynamix/template. php:50 Stack trace: #0 /usr/local/emhttp/plugins/dynamix/template.php(50): extract(false) #1 {main} thrown in /usr/local/emhttp/plugins/dynamix/template.php on line 50 [14-Nov-2025 20:30:30 America/New_York] PHP Fatal error: Uncaught TypeError: extract(): Argument #1 ($array) must be of type array, false given in /usr/local/emhttp/plugins/dynamix/template. php:50 Stack trace: #0 /usr/local/emhttp/plugins/dynamix/template.php(50): extract(false) #1 {main} thrown in /usr/local/emhttp/plugins/dynamix/template.php on line 50 [14-Nov-2025 20:31:22 America/New_York] PHP Fatal error: Uncaught TypeError: extract(): Argument #1 ($array) must be of type array, false given in /usr/local/emhttp/plugins/dynamix/template. php:50 Stack trace: #0 /usr/local/emhttp/plugins/dynamix/template.php(50): extract(false) #1 {main} thrown in /usr/local/emhttp/plugins/dynamix/template.php on line 50 [14-Nov-2025 20:31:29 America/New_York] PHP Fatal error: Uncaught TypeError: extract(): Argument #1 ($array) must be of type array, false given in /usr/local/emhttp/plugins/dynamix/template. php:50 Stack trace: #0 /usr/local/emhttp/plugins/dynamix/template.php(50): extract(false) #1 {main} thrown in /usr/local/emhttp/plugins/dynamix/template.php on line 50 [14-Nov-2025 20:32:42 America/New_York] PHP Fatal error: Uncaught TypeError: extract(): Argument #1 ($array) must be of type array, false given in /usr/local/emhttp/plugins/dynamix/template. php:50 Stack trace: #0 /usr/local/emhttp/plugins/dynamix/template.php(50): extract(false) #1 {main} thrown in /usr/local/emhttp/plugins/dynamix/template.php on line 50 So yeah, I'd assume this has something to do with one of the Dynamix plugins that deal with file changes. I'm going to remove almost all of them I have installed, for now: Dynamix File Integrity Dynamix S3 Sleep Dynamix System Buttons Dynamix System Information Dynamix Cache Directories I also have Dynamix SCSI Devices but given it's rename functions I don't want to risk deleting it quite yet. My goal is to do some more file movements and then see what the results are, then respond to this thread (if I remember!) Thanks to everyone who's reported and helped, so far. ETA: One more data point -- when this 1st occurred, I tried a different browser that I'd never logged into UnRAID onto before. I was able to load the login page, but hit the 500 error after login. Don't know if that helps anyone, but wanted to point that out. morningstar-diagnostics-20251114-2049.zip
-
Thank you! Worked like a charm.
-
Upgraded Unraid to latest, not anything else. No drives have been moved in any way, yet.
-
Hi. I have to apologize on multiple counts. I upgraded, shut down the server, and left home to spend time with family, so won't be able to add the diag file until I get back Monday. If you want to ignore the rest of this reply until I can add the file, I understand. I say this because I clearly am causing frustrations I do not mean to, by not explaining fully and using incorrect terms instead of fully documenting my idea. Again, my apologies for that, and I will ensure I upload the requested diagnostics ASAP upon my return to my home. That said, I ask for your patience as I attempt to clarify my situation and goals: 1) I have an Array with 1 8TB parity drive, currently, and a mix of 4 and 8 TB drives, a mix of SAS and SATA, for the data drives. 2) I have 3 8TB SAS drives, not installed in anything currently, that I would like to use in this Array, in the following ways: 2a) Use 2 of the 8TB drives to replace 2 of my existing 4TB drives, and 2b) Use the last 8TB drive to become a 2nd parity drive; it will not replace any existing drive 3) I have one more SAS connector for a drive, so cannot connect two more SAS drives to the server/Array. It will, obviously, need to become the connector for the 2nd Parity. To hopefully clarify why I referred to shrinking the array for the above process -- as I said in my original post and above, I used that "shrink array" process, from that wiki page of "shrinking the array," to do this a few years ago, successfully. That time, I "shrank" the Array by three 2TB SAS data drives, physically removing said drives, then adding three 4TB SAS drives into the same Array. I did it in this fashion because that wiki page says explicitly that "This method is best if you are removing more than one drive" which is my plan, per above, and also given connection limitations. That is why I linked to that page, and talked about shrinking the array. The idea I have this time is to do 2a) above by "shrinking" out the two 4TB SAS drives currently attached and in the Array, physically removing the drives, and then adding the 2 new 8TB drives in. Along with, of course, adding a 3rd 8TB drive for a 2nd Parity, as I mention above. And I'm trying to ask if there's a better approach that using that wiki page, esp. given the age of that wiki page and the goal to add the 2nd Parity. Given that your guidance leverages using "New Config" once the new drives are added, which aligns with Step 4 in the wiki documentation, I suspect, at the end of the day, it is still the right procedure, and this confusion was due to my clumsy words more than anything technical. I hope this clarifies my goals w/o adding more frustration to the discussion. Thank you, all, for your time and attention, and again I shall add the diagnostics as soon as possible.
