





Kulis
Members
-
Joined
-
Last visited
-
I don't know how it happened, but I managed to fix it. I upgraded to 7.3.2, but it didn't work—I still had nothing in /user. I shut down Docker and the VM, removed Valut, and then ran the update to 7.3.3 again. Everything came back!
-
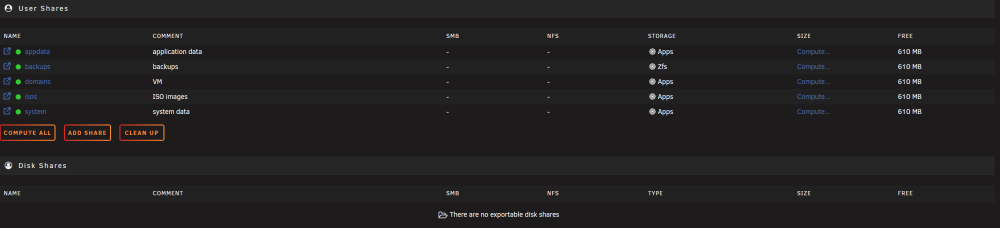
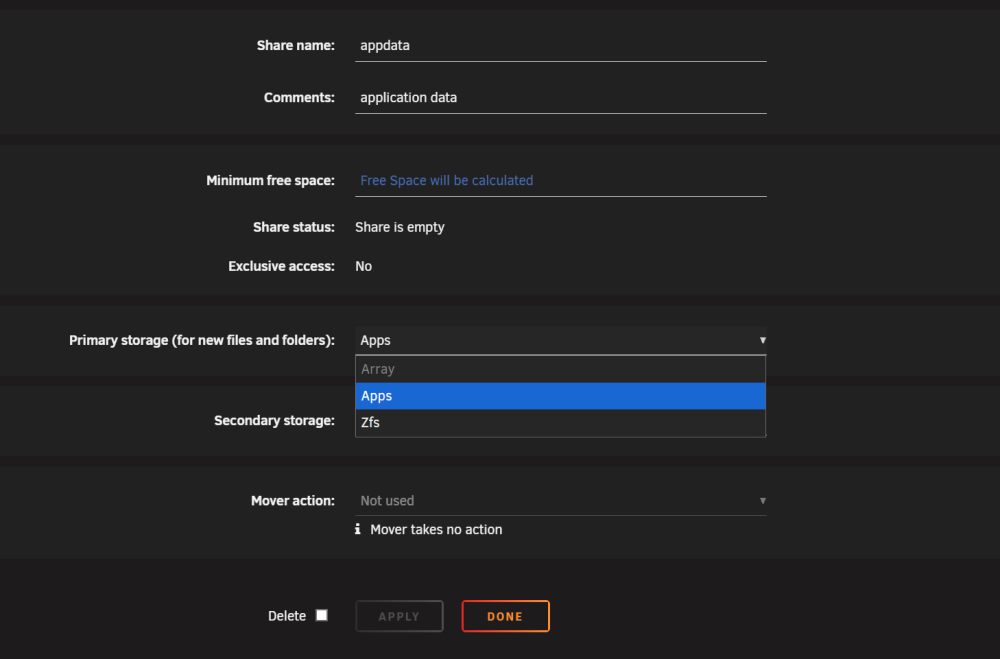
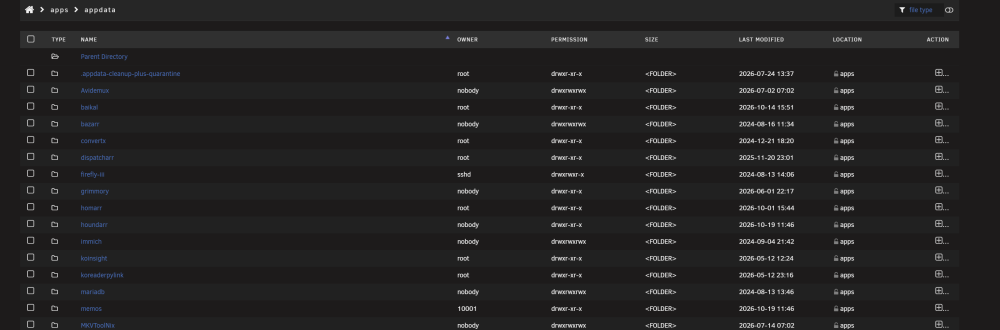
After updating to version 7.3.3, all my Docker containers disappeared, and my directories are no longer in the /mnt/user directory. Has anyone else had a similar problem and know how to fix it so that everything in Share is just like it was before the update?
-
@PanicMechanic007 Am I to understand that your plugin will be a separate tool?
-
Today it's even worse—why is Valut an unaccepted plugin?: The plugin vault.plg is not known to Community Applications and is possibly incompatible with your server As a general rule, if the plugin is not known to Community Applications, then it is not compatible with your server. It is recommended to uninstall this plugin
-
Why is Valut suddenly adding files to the directory: /mnt/user/.vault ? This causes me to get the following error: Invalid folder vault-fuse contained within /mnt Generally speaking, most times when other folders get created within /mnt it is a result of an improperly configured application. This error may or may not cause issues for you More Information
-
Could you please tell me how I should format this drive now so that it can be used as a boot drive for the Unraid OS?

-
Your instructions work! Now the final step is to reimport the pool without that subpool, to do that: stop the array on main, click on the first device for that pool and then "remove pool" back on main, create a new pool with the same name and the new number of slots assign the remaining pool device(s), it can be in any order, they will be sorted at array start leave the filesystem set to auto start the array to import the pool
-
@JorgeB Should I do this on the drives that are currently running, or should I stop them?
-
Good morning, I'd like to disconnect the NVMe drive that serves as a cache for the ZFS pool: pool: zfs state: ONLINE scan: scrub repaired 0B in 14:11:27 with 0 errors on Wed Jul 1 13:11:28 2026 config: NAME STATE READ WRITE CKSUM zfs ONLINE 0 0 0 raidz2-0 ONLINE 0 0 0 /dev/sdf1 ONLINE 0 0 0 /dev/sdg1 ONLINE 0 0 0 /dev/sdh1 ONLINE 0 0 0 /dev/sdi1 ONLINE 0 0 0 /dev/sdj1 ONLINE 0 0 0 /dev/sdk1 ONLINE 0 0 0 /dev/sda1 ONLINE 0 0 0 /dev/sdb1 ONLINE 0 0 0 /dev/sdc1 ONLINE 0 0 0 /dev/sdd1 ONLINE 0 0 0 cache /dev/nvme0n1p1 ONLINE 0 0 0 errors: No known data errors Can you tell me how to do this? After stopping the pool and trying to detach the disk, I get a "missing" message: Ultimately, I wanted to use the drive as a bootable drive for Unraid.

-
Unfortunately, when I try to revert to the previous version, it throws errors left and right.
-
@sdchoni When I do that, I get a message in the log saying that the migration failed.
-
@Djoss The problem is described here: I have Cloudflare set up, and the certificate is configured in Nginx via Cloudflare. Logi: │ │ │ Application: Nginx Proxy Manager │ │ Application Version: 2.14.0 │ │ Docker Image Version: 26.03.1 │ │ Docker Image Platform: linux/amd64 │ │ │ ╰――――――――――――――――――――――――――――――――――――――――――――――――――――――――――――――――――――――╯ [cont-init ] 89-info.sh: terminated successfully. [cont-init ] all container initialization scripts executed. [init ] giving control to process supervisor. [supervisor ] loading services... [supervisor ] loading service 'default'... [supervisor ] loading service 'app'... [supervisor ] loading service 'nginx'... [supervisor ] loading service 'logmonitor'... [supervisor ] service 'logmonitor' is disabled. [supervisor ] loading service 'logrotate'... [supervisor ] service 'logrotate' is disabled. [supervisor ] loading service 'cert_cleanup'... [supervisor ] all services loaded. [supervisor ] starting services... [supervisor ] starting service 'nginx'... [supervisor ] starting service 'app'... [supervisor ] all services started. [cert_cleanup] ---------------------------------------------------------- [cert_cleanup] Let's Encrypt certificates cleanup - 2026/03/16 12:56:50 [cert_cleanup] ---------------------------------------------------------- [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-9/fullchain2.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-9/privkey2.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-9/chain2.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-9/cert2.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-2/fullchain9.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-2/chain9.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-2/cert9.pem. [cert_cleanup] Keeping /etc/letsencrypt/archive/npm-2/privkey9.pem. [cert_cleanup] 8 file(s) kept. [cert_cleanup] 0 file(s) deleted. [app ] [3/16/2026] [12:56:50 PM] [Global ] › ℹ info Using configuration from file: ./config/production.json [app ] [3/16/2026] [12:56:50 PM] [Migrate ] › ℹ info Current database version: none [app ] [3/16/2026] [12:56:50 PM] [Setup ] › ℹ info Logrotate Timer initialized [app ] [3/16/2026] [12:56:50 PM] [Setup ] › ℹ info Logrotate completed. [app ] [3/16/2026] [12:56:50 PM] [Global ] › ℹ info IP Ranges fetch is enabled [app ] [3/16/2026] [12:56:50 PM] [IP Ranges] › ℹ info Fetching IP Ranges from online services... [app ] [3/16/2026] [12:56:50 PM] [IP Ranges] › ℹ info Fetching https://ip-ranges.amazonaws.com/ip-ranges.json [app ] [3/16/2026] [12:56:50 PM] [IP Ranges] › ℹ info Fetching https://www.cloudflare.com/ips-v4 [app ] [3/16/2026] [12:56:51 PM] [IP Ranges] › ℹ info Fetching https://www.cloudflare.com/ips-v6 [app ] [3/16/2026] [12:56:51 PM] [SSL ] › ℹ info Let's Encrypt Renewal Timer initialized [app ] [3/16/2026] [12:56:51 PM] [SSL ] › ℹ info Renewing SSL certs expiring within 30 days ... [app ] [3/16/2026] [12:56:51 PM] [IP Ranges] › ℹ info IP Ranges Renewal Timer initialized [app ] [3/16/2026] [12:56:51 PM] [Global ] › ℹ info Backend PID 560 listening on port 3000 ... [app ] [3/16/2026] [12:56:51 PM] [SSL ] › ℹ info Completed SSL cert renew process My settings router: My docker parametrs: docker run -d --name='NginxProxyManager' --net='dockernet' --pids-limit 2048 -e TZ="Europe/Warsaw" -e HOST_OS="Unraid" -e HOST_HOSTNAME="KulisUnRaid" -e HOST_CONTAINERNAME="NginxProxyManager" -e 'USER_ID'='99' -e 'GROUP_ID'='100' -e 'UMASK'='0000' -e 'APP_NICENESS'='0' -e 'DISABLE_IPV6'='0' -l net.unraid.docker.managed=dockerman -l net.unraid.docker.webui='http://[IP]:[PORT:8181]' -l net.unraid.docker.icon='' -p '7818:8181/tcp' -p '1880:8080/tcp' -p '18443:4443/tcp' -v '/mnt/user/appdata/NginxProxyManager':'/config':'rw' 'jlesage/nginx-proxy-manager'
-
I installed the latest version and am getting an SSL handshake failed error Error code 525 Even the website is having the same problem: Application Site: https://nginxproxymanager.jc21.com Is there any way to fix this?
-
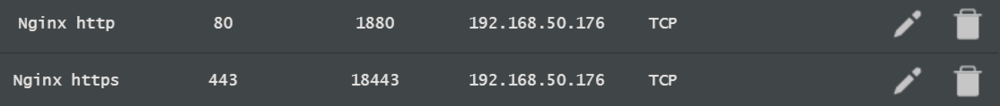
I don't understand. Can you tell me exactly what I need to change to make this work? Everything was fine until today. My redirects on the router look like this: In Unraid, my settings are as follows: I see that Nginx had some kind of update, so I generated new certificates, but it still isn't working.

-
For now, I see that whatever you set at the start is what you get. So I don't see any possibility of synchronizing both Plex and Jellyfin.





