





potjoe
Members
-
Joined
-
Last visited
-
Thank you for your answer! Plex logs shows that "loudness analysis" failed for a media at the exact time of OOM. Plex seems aware of the issue and working on a fix : https://forums.plex.tv/t/loudness-analysis-grows-to-10-gb-ram-and-triggers-host-oom-killer/943677/24 For the time being, I'll add --memory=6G parameter.
-
Hi everyone, I've been having out of memory errors for the past month, despite my server have been running smoothly with the same services for years. Last night, it occured again, killing plex transcoder service (I don't know what it was transcoding at 4 am...). I wonder if the issue comes from this container, or if it is just the service which is killed to free some low priority ram on the system. Thank you for your help monalisa-diagnostics-20261025-0914.zip
-
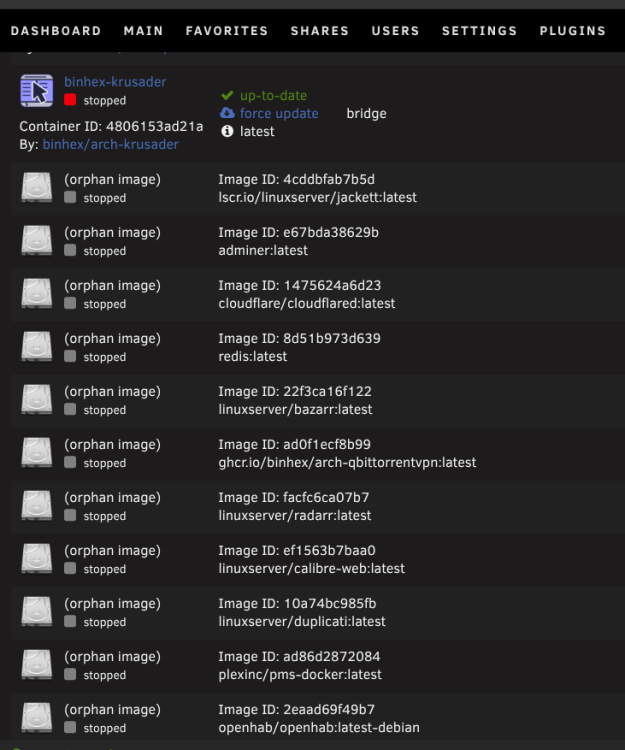
So it did the trick. I removed the old entries (I had to do it multiple times..) and added back four missing containers, after a reboot some other container went missing. Each reboot presented new faulty containers... I followed your procedure as long as orphan images appeared, it seems okay now! Thank you for your help.
-
Following my investigations, something is weird : the missing containers are not the same between each reboot in 7.3.4. Sometimes Plex starts, the next reboot it is an orphaned image.
-
Yes I had seen your previous answer. So I tried the following procedure : 1) Downgrade to 7.2.4. All containers are present and working. 2) Remove the RAM-DISK-Dockerlog plugin. 3) Remove the ram disk section added in /boot/config/go~ and reboot. 4) Delete the folder /mnt/cache/appdata/containers_backup. 5) Update to 7.3.4. But unfortunately, containers are still missing... monalisa-diagnostics-20261023-1417.zip
-
Thank you, here it is. Diagnostics after the update. monalisa-diagnostics-20261023-1209.zip
-
Hi, I've been trying to update to 7.3.4 from 7.2.4 last night, but after the update, half of my docker containers were deleted, resulting with orphaned images. I had to revert back to 7.2.4 for the time being. Is there a way to prevent this behaviour ? Thank you for your help.
-
Hello @binhex . I've been using this container for years with openVPN and PIA with no issues at all. Recently, I switched to wiregard, and I updated the container because the template was not up to date anymore. In a nutshell, I had to switch network type from bridge to br0 and assign an ip, and I now feel a bit nervous because my true ip address may appear in Qbittorent WebUi... XXX.XXX.XXX.XXX How is it possible, and is there a risk for a leak using br0 as a network interface ? Edit: Forgot to mention, I switched to br0 because I could not get wiregard working. In bridge mode, the container is stuck at [info] Trying to connect to the PIA WireGuard API on 'nl-amsterdam.privacy.network'... and webUI is never accessible.
-
Hello there! First time for me, a drive seems to be slowly failing. A week ago, I had 3 read erros (Reported uncorrect), I decided to wait and see. Yesterday, received a notification of 8 reallocated sectors count, so I thought it is time to replace the drive (is it ?). My current array is made of : 3 TB Parity drive (healthy) 3 TB Data drive (healthy) 3 TB Data drive (failing) 1 TB Data drive (healthy) I found a 4TB drive as a replacement, but it is larger than my current parity drive. How to handle the disk replacement going forward ? Thank you for your help. monalisa-diagnostics-20260202-1508.zip
-
Thank you for your help, I will try these different steps and keep you updated (change ports then format). It is now connected directly to the internal USB 2.0 header with an adapter, I'll first try to reseat it / then change it. I do have a quite recent backup thanks to unraid connect.
-
I managed to bypass the broken menu and to go directly to the Url of diagnose page, it worked. Here is the diagnostic. Sorry for the time lost monalisa-diagnostics-20240327-1924.zip
-
root@MonaLisa:~# df -h Filesystem Size Used Avail Use% Mounted on rootfs 7.7G 1.7G 6.1G 22% / tmpfs 32M 1.9M 31M 6% /run /dev/sda1 29G 754M 29G 3% /boot overlay 7.7G 1.7G 6.1G 22% /lib/firmware overlay 7.7G 1.7G 6.1G 22% /lib/modules devtmpfs 8.0M 0 8.0M 0% /dev tmpfs 7.8G 0 7.8G 0% /dev/shm cgroup_root 8.0M 0 8.0M 0% /sys/fs/cgroup tmpfs 128M 100M 29M 78% /var/log tmpfs 1.0M 0 1.0M 0% /mnt/disks tmpfs 1.0M 0 1.0M 0% /mnt/remotes tmpfs 1.0M 0 1.0M 0% /mnt/addons tmpfs 1.0M 0 1.0M 0% /mnt/rootshare /dev/md1 2.8T 2.6T 172G 94% /mnt/disk1 /dev/md2 2.8T 2.6T 179G 94% /mnt/disk2 /dev/md3 932G 714G 218G 77% /mnt/disk3 /dev/sdf1 466G 137G 329G 30% /mnt/cache /dev/sdg1 239G 43G 197G 18% /mnt/cache_nvme shfs 6.4T 5.9T 568G 92% /mnt/user0 shfs 6.4T 5.9T 568G 92% /mnt/user /dev/loop2 40G 20G 20G 51% /var/lib/docker tmpfs 7.8G 324M 7.5G 5% /var/lib/docker/containers /dev/loop3 1.0G 4.4M 905M 1% /etc/libvirt Here it is. Thank you for your help!
-
Hi all, Accessing the Web UI, I noticed today some big troubles in my server. I do not live in the same location, so I don't know when it started. The webUI is off, displaying failed to open stream everywhere, most of options and pages are unavailable (I cannot access diagnostic or logs through UI). The USB key seems to be blacklisted OR offline, but I wanted to post here before attempting a reboot or anything. Here are some screenshots. Could you provide me with instructions to diagnose / fix its current state ? I've been running unraid for years without any issue.


-
Hi, For many months, I've had an issue with my server having 100% CPU load that I've been unable to troubleshoot since it begun, and this is why I'm finally posting here. Netdata reports high iowait when these spikes are happening. Bios is up to date, File integrity is not used in the system. I've removed every unused docker, reduced my ram usage by 10%, and still, it is happening again, but less often (it was every fifteen minutes, now it's once a day). I've tried many times tracing it down with iotop / htop, but I have not been able to find the culprit. When it happens, I noticed that cache drive read speed is really high (more than 300 mb/s). I hope someone can help me figure it out, thank you for your time. Diagnostic file : monalisa-diagnostics-20230319-0933.zip
-
This unraid template should be revised, as well as the configuration.py default file. Noticed issues : When initializing the container for the first time, there is an error l. 246 in configuration.py. A "}" at the end of the line is causing an error. It conflicts with REMOTE_AUTH_DEFAULT_PERMISSIONS default value, this character should not be already there. Most default values for Environment Variables are incorrectly set. Currently, variables values are set to be the ENV variable name by default, which is causing a lot of errors during initialization. Indeed, since configuration.py is written when the container is started for the first time, having wrong values does not prevent the container to start and result in a config file with many errors, which has to be corrected later on. Instead, ENV var that are required to be set by user should be empty to prevent the container to start if not set. According to https://docs.linuxserver.io/images/docker-netbox, default values should be set as follow : SUPERUSER_EMAIL* : SUPERUSER_EMAIL 'empty' SUPERUSER_PASSWORD*: SUPERUSER_PASSWORD 'empty' ALLOWED_HOST*: ALLOWED_HOST 'empty' DB_NAME*: DB_NAME netbox DB_USER*: DB_USER 'empty' DB_PASSWORD* : DB_PASSWORD 'empty' DB_HOST*: DB_HOST postgres DB_PORT*: DB_PORT 5432 REDIS_HOST*: REDIS_HOST redis REDIS_PORT*: REDIS_PORT 6379 REDIS_PASSWORD: REDIS_PASSWORD 'empty' REDIS_DB_TASK*: REDIS_DB_TASK 0 REDIS_DB_CACHE*: REDIS_DB_CACHE 1 BASE_PATH: BASE_PATH 'empty' REMOTE_AUTH_ENABLED: REMOTE_AUTH_ENABLED False REMOTE_AUTH_BACKEND: REMOTE_AUTH_BACKEND netbox.authentication.RemoteUserBackend REMOTE_AUTH_HEADER: REMOTE_AUTH_HEADER HTTP_REMOTE_USER REMOTE_AUTH_AUTO_CREATE_USER: REMOTE_AUTH_AUTO_CREATE_USER False REMOTE_AUTH_DEFAULT_GROUPS: REMOTE_AUTH_DEFAULT_GROUPS [] REMOTE_AUTH_DEFAULT_PERMISSIONS: REMOTE_AUTH_DEFAULT_PERMISSIONS {} Currently, REDIS_PASSWORD ENV var is 'required' in the template. It should not, since it is optionnal. As a general concern, changes in the UI does not reflect on the configuration file, since it is only written the first time the container start. Isn't there a way to pass Environnement variable to the config after it has been created ?




