





J89eu
Members
-
Joined
-
Last visited
-
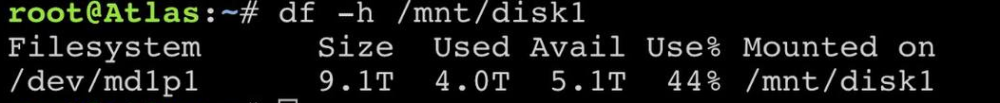
Hi all, Struggling with the next steps on this one. I have had a disk die - (disk1) so I proceeded to move everything off it to other disks in the array as I cannot afford a new drive currently, this completed but after it did, the emulated disk showed 4TB still in use. I had started to troubleshoot this but didn't get far as I had to go out today, I did manage to get a screenshot showing the usage below, despite there being literally nothing on this disk when looking into it: What was also interesting and a bit scary was that when I was moving data off the drive, disk6 started to throw up UDMA CRC errors. I wasn't massively worried about this at the time as I understand these are generally cable issues so I purchased another breakout cable and planned to replace it but combined with the latest issue I am now a bit worried! So I came home and my Plex docker seemed dead, it was running so I restarted it, same issue, I then checked the log and could see the following: 2026-10-11 16:29:10,132 DEBG 'start-script' stderr output: chmod: changing permissions of '/config/Plex Media Server/Codecs/EasyAudioEncoder-6a4213e165f8ac3d108a346e-linux-x86_64': Input/output error I then checked other docker containers and half are not running, half are, but cannot be used. So I am suspecting some docker image corruption perhaps... I then just thought let's reboot the server to see if perhaps the disk1 usage thing clears and it maybe fixes the issue if some paths are looking at disk1. When it came back up, disk1 started to show "Unmountable: wrong or no file system" I stopped the array and started it again, with disk1 still in but same issue. I am wondering if I should replace the cable that disk6 runs on and then create a new hardware profile with all the drives moved up 1 so I can then scrap disk1 but I am a little worried with the docker issue on top and wanted to run it by you guys before I likely make anything worse! I've also attached diagnostics as it currently stands. I thought I'd do some less intrusive testing and did a 'touch' on disk6 and it shows input/output error on that disk when I try, the other disks work fine so perhaps the dockers won't start successfully as they're trying to write data to disk6 first and it's not allowing it so they just break? atlas-diagnostics-20261011-1701.zip
-
Ok resolved that, I need to just create a new disk config, now back up and running, thanks all
-
So I have managed to get my server up mostly from a backup, however, my drive setup wasn't stored, I have that, so that's OK but the cache is defaulting to BTRFS whereas I was using a pool of 2 drives on ZFS, I can't seem to change it from BTRFS to ZFS though and I'm worried about changing something wrong and deleting what's on the disks, if anyone can help? Looking in my new disk.cfg I can see disks are marked btrfs but not sure if I can just change this if I can work out which disks the cache ones are and just set zfs? diskFsType.7="btrfs" Though based on these numbers I feel these are just the hard drives and not the SSD cache drives. I also had an idea to start the array without the cache drives, mount them as unassigned devices and then copy the contents off, and create the new cache pool but I cannot start the array like that and I'm worried that erasing the "cache settings" will erase my disks even if they are unassigned I get this warning


-
I do have one that is just files, from the backup plugin but the restore process wants a zip file, I tried to zip that up and flash but it didn't boot so I imagine I am missing something?
-
I mean, it's here, but not sure what to look at, it just appears to be reset perhaps? I am in UK timezone (BST) and my workgroup is not WORKGROUP. Those are the stand out ones are least. # Generated settings: NAME="Tower" timeZone="America/Los_Angeles" COMMENT="" SECURITY="user" WORKGROUP="WORKGROUP" DOMAIN="" DOMAIN_SHORT="" hideDotFiles="no" enableFruit="yes" USE_NETBIOS="no" localMaster="yes" serverMultiChannel="no" USE_WSD="yes" WSD_OPT="" WSD2_OPT="" USE_NTP="no" NTP_SERVER1="" NTP_SERVER2="" NTP_SERVER3="" NTP_SERVER4="" DOMAIN_LOGIN="Administrator" DOMAIN_PASSWD="" SYS_MODEL="Custom" SYS_ARRAY_SLOTS="0" USE_SSL="no" PORT="80" PORTSSL="443" LOCAL_TLD="local" BIND_MGT="no" USE_TELNET="no" PORTTELNET="23" USE_SSH="no" PORTSSH="22" USE_UPNP="no" START_PAGE="Main"
-
Hi all. Had my server seemingly lock up so gave it a hard reboot, upon it coming back up the hostname in the login box shows "Tower" where it used to show Atlas (what I call my server) and my username and password no longer works. I then shut down, removed the USB stick and removed the shadow and smbpasswd files, powered back up and it prompted for new details. I put in what I wanted, it took them, then took me to the login screen and won't let me in still. I have tried SSH and that doesn't even allow a connection so appears to be disabled whereas it wasn't previously. Seems something has reset but won't let me in to asses the damages.. Help?!
-
Yep that fixed it, not using the iGPU for anything I wasn't expecting that to work, especially as the Discord seemed to agree! Nonetheless we are now working.
-
Hi all, just branching this off from the 6.12 release. Since updating my system performance has gone insanely bad, to the point the web interface is not usable if I perform a simple task like erasing a drive... I've been talking about this loosely in the Unraid discord but seems no one is able to really concentrate on the one issue to help, and I get that, there's a lot of people asking questions that overlap, it is what it is. So I updated from a working system, no pre-existing issues. I then noticed my server seemed dead on first boot, no screen output, no ping etc, but I had to go for lunch, when I came back it was up and working. Logged in and then went to set up my cache from btrfs to ZFS and this is when I noticed these huge pauses. To cut a long story short, I have no VMs, no docker containers etc running. System is an 11400 Intel so not old nor underpowered for the task at hand! Attached CPU usage when just asking it to format a drive, being the first peak (set to 5M) and then after startng the array with also the TOP output from console. Diagnostics also attached. I have also updated my BIOS since having the issue, diagnostics are from before this. I've also recreatd a fresh USB image and transferred over my config, same issue. I have tried safe mode with no GUI and plugins, issue remains. Downgrading to 6.11.5 immediately resolves the issue. atlas-diagnostics-20230619-0928.zip


-
Hi all, since updating my system performance has gone insanely bad, to the point the web interface is not usable if I perform a simple task like erasing a drive... I've been talking about this loosely in the Unraid discord but seems no one is able to really concentrate on the one issue to help, and I get that, there's a lot of people asking questions that overlap, it is what it is. I'm happy to separate this out to an entirely new thread if needed... So I updated from a working system, no pre-existing issues. I then noticed my server seemed dead on first boot, no screen output, no ping etc, but I had to go for lunch, when I came back it was up and working. Logged in and then went to set up my cache from btrfs to ZFS and this is when I noticed these huge pauses. To cut a long story short, I have no VMs, no docker containers etc running. System is an 11400 Intel so not old nor underpowered for the task and hand! This is the CPU usage when just asking it to format a drive, being the first peak (set to 5M) and then after startng the array with also the TOP output from console. Diagnostics also attached. EDIT: To add I just downgraded back to 6.11.5 and all my problems disappeared to this seems to be an issue specific to 6.12 for me atlas-diagnostics-20230619-0928.zip


-
Herein lies my issue, stupid me! I was adding it to extra parameters. Special thanks to Marius on the Discord for correcting me. I do feel rather embarrassed.
-
Hey GilbN, I'm on your Discord if you wanted to chat there about it but appreciate you are not my technical support person! If you mean this line then yes I did do that:
-
Hi, thanks for getting back to me so fast!! Here's my variables, they all seem correct to me: Also my default is indeed set: Of note is that I also get no SMART data, I did add the telegraf.conf option as advised in the 1st post. Additionally I'm on the latest 6.9 Beta if that makes any difference


-
Hi all I've followed all the dependancies etc but not getting any disks showing, I haev the input source etc all set right... Not sure what's going on

-
Hi all I was having an issue with the docker losing all stats when a setting change was made, I had this with the Unifi docker and it was caused by the interface settings. I noticed that I was not running this docker on my custom interface so I swapped to that but it wouldn't start, I managed to get it working using these settings: "Network type" I had to keep as br0 rather than my custom interface called "atlas" but I was able to get it started by settings the INTERFACE as "atlas" and the "ServerIP" as the custom IP I wanted, does that look right? Hopefully it will fix my stats being reset each time too.

-
Hi, for the Telegraf docker, how can I install the input plugin APCUPSD? https://github.com/influxdata/telegraf/tree/master/plugins/inputs/apcupsd Seems it's part of the standard feature set but I can't see it in the telegraf conf file Cheers


