nraygun
Members
-
Joined
-
Last visited
Everything posted by nraygun
-
Any other ideas? Just concerned that if this is not working correctly, what else could be going wrong?
-
I also tried changing each setting, then setting it back, then rebooted. Still shows the reboot prompt.
-
Tried that. Twice. Still get the notice to reboot upon looking at the VM Manager area. It's in this state now. I'll reboot again to get rid of it. Diags attached. (Appreciate the help!) server-diagnostics-20220707-2013.zip
-
Not that I'm aware of.
-
I tried a few things and still get the reboot message at the top: Copied the domain.cfg to domain.old, deleted the file, then had unRaid recreate the file. I rebooted, then went to the VM Manager area, and it still has the reboot message at the top. Tried uninstalling the My Server plugin (read somewhere that was causing issues for someone) and I still get the message. Tried a different browser - PaleMoon in MX Linux
-
I see the time/date stamp for the domain.cfg file change when I visit that area and don't change anything. Using diff, they contain the same content. Hmmm...
-
If I reboot it goes away. Until I hit the VM Manager icon again. When I look at it, it's in Basic View. root@server:~# cat /boot/config/domain.cfg SERVICE="enable" IMAGE_FILE="/mnt/user/system/libvirt/libvirt.img" IMAGE_SIZE="1" DEBUG="no" DOMAINDIR="/mnt/user/domains/" MEDIADIR="/mnt/user/isos/" VIRTIOISO="/mnt/user/isos/virtio-win-0.1.190-1.iso" BRNAME="br0" VMSTORAGEMODE="auto" HOSTSHUTDOWN="shutdown" TIMEOUT="180"
-
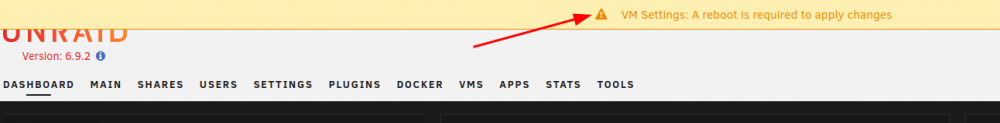
And now it's on every page. I didn't change anything - I just clicked the VM Manager icon.
-
No. I've been on 6.9.2 since it came out. I don't recall if I had this issue on the prior version. And I'm holding off on going to 6.10.3 given recent events. Maybe going to the new version will clear this up?If I simply go to the VM Manager page under the Settings tab, I immediately get prompted to reboot the server even though nothing was changed. I'm told this is not normal. Can someone confirm this is not normal behavior and help me understand why I see this behavior?Will this fix allow the posting of a DMAR error when there really is a DMAR error?Right there with you. I just went back to 6.9.2 until this all gets sorted out. Can't say I was comfortable with the thought that I might not have data corruption. I also had a problem with My Servers that is now resolved now that I went back to 6.9.2. It was giving me an unraid-api error. Thanks and good luck to the team investigating this DMAR error situation!Well, wait a minute. I had blanked out the tg3.conf on my Dell R710 which uses the bnx2 module. Before blanking it out, I was getting lots (screen fulls) of DMAR errors. I get 2 on boot but then none (so far) after that. Shouldn't I have had NO errors? Is there something else going on here?Thanks for the quick response. I was getting a ton more of those errors before I blanked out tg3.conf. I just got a weird response from the system - the logs would not display and I could not get to the command line. Also, the login area said something about "unraid-api" problems and had an option to restart so I did. I'll just keep an eye on things. If I get another DMAR error, I'll just roll back.Any thoughts on the other part of my post where I now only see 2 DMAR:ERRORs on boot? I haven't seen any more of these errors overnight. Should I continue using 6.10.2?There's mention in the release notes of the tg3 module causing problems. So I followed the directions to blank it out (even though it appears my NIC uses the bnx2 driver). I now only see 2 of the errors. And I think I need vt-d turned on for GPU passthru. Am I good to go?Upgraded to 6.10.2 from 6.9.2 and it mostly went OK. I had to get rid of a few plugins that were no longer supported and replace them with different ones. I also see in the boot screens a number of "DMAR: ERROR: DMA PTE for vPFN" messages. I have a Dell R710 with NetXtreme II BCM5709 Gigabit Ethernet (rev 20) NICs that seem to use the bnx2 drivers. I created the blank tg3.conf anyway. Now when I rebooted, I only see 2 DMAR:ERRORs. Am I good to go or is there still a problem? My VMs with GPU passthu seem to work as does everything else. Worried about data corruption as mentioned in the release notes.I just upgraded to 6.10.2 too and I see this error in the console. I've had vt-d turned on since I've had this R710 server and have not had any stability issues or corruption as far as I can tell. What else will disabling vt-d cause? I seem to recall turning it on for some reason. Maybe for GPU passthru?I got on a Discord channel with the developers of the container and found that they had a parameter defaulting to a value that was causing my problem. To resolve it, just remove the /dev/dri: parameter in the container.@xavierda Did you get this fixed? My problem came back. All I get is a blank screen.I'm using the CA User Scripts plugin with some scripts that are scheduled to run in the background. Works great for my backup script. There's a "Show log" button for the script, but it only shows the last 41 lines or so from the log. I know I can go into the full log at /tmp/user.scripts/tmpScripts/scriptname/log.txt, but is there a way to lengthen the number of lines that the "Show log" button shows?Cool. That's what I thought. Thanks!I'm testing out hotswapping an unassigned drive I use for daily backups. Overall, it seemed to work. I unmounted the unassigned drive, spun it down, pulled it out, saw that it was gone, then reinstalled it. It then came back and mounted as before. So far, so good. However, in the log after the physical removal, I see this: Mar 6 10:55:49 server kernel: sd 3:0:0:0: [sdc] Synchronize Cache(10) failed: Result: hostbyte=0x01 driverbyte=0x00 Should I be concerned with this? Here's the rest of the log during the hotswap event: Mar 6 10:54:33 server unassigned.devices: Unmounting partition 'sdc1' at mountpoint '/mnt/disks/backup1'... Mar 6 10:54:33 server unassigned.devices: Synching file system on '/mnt/disks/backup1'. Mar 6 10:54:33 server unassigned.devices: Unmount cmd: /sbin/umount '/dev/sdc1' 2>&1 Mar 6 10:54:33 server kernel: XFS (sdc1): Unmounting Filesystem Mar 6 10:54:36 server emhttpd: read SMART /dev/sdc Mar 6 10:54:36 server unassigned.devices: Successfully unmounted 'sdc1' Mar 6 10:54:43 server emhttpd: spinning down /dev/sdc Mar 6 10:55:47 server kernel: sd 3:0:0:0: device_block, handle(0x0009) Mar 6 10:55:49 server kernel: sd 3:0:0:0: device_unblock and setting to running, handle(0x0009) Mar 6 10:55:49 server kernel: sd 3:0:0:0: [sdc] Synchronizing SCSI cache Mar 6 10:55:49 server emhttpd: read SMART /dev/sdc Mar 6 10:55:49 server kernel: sd 3:0:0:0: [sdc] Synchronize Cache(10) failed: Result: hostbyte=0x01 driverbyte=0x00 Mar 6 10:55:49 server kernel: mpt2sas_cm0: mpt3sas_transport_port_remove: removed: sas_addr(0x4433221102000000) Mar 6 10:55:49 server kernel: mpt2sas_cm0: removing handle(0x0009), sas_addr(0x4433221102000000) Mar 6 10:55:49 server kernel: mpt2sas_cm0: enclosure logical id(0x5d4ae5207ae4de00), slot(1) Mar 6 10:55:50 server rc.diskinfo[10694]: SIGHUP received, forcing refresh of disks info. Mar 6 10:59:27 server kernel: scsi 3:0:5:0: Direct-Access ATA WDC WD20EFAX-68F 0A82 PQ: 0 ANSI: 6 Mar 6 10:59:27 server kernel: scsi 3:0:5:0: SATA: handle(0x0009), sas_addr(0x4433221102000000), phy(2), device_name(0x0000000000000000) Mar 6 10:59:27 server kernel: scsi 3:0:5:0: enclosure logical id (0x5d4ae5207ae4de00), slot(1) Mar 6 10:59:27 server kernel: scsi 3:0:5:0: atapi(n), ncq(y), asyn_notify(n), smart(y), fua(y), sw_preserve(y) Mar 6 10:59:27 server kernel: scsi 3:0:5:0: qdepth(32), tagged(1), scsi_level(7), cmd_que(1) Mar 6 10:59:27 server kernel: sd 3:0:5:0: Power-on or device reset occurred Mar 6 10:59:27 server kernel: sd 3:0:5:0: Attached scsi generic sg3 type 0 Mar 6 10:59:27 server kernel: end_device-3:5: add: handle(0x0009), sas_addr(0x4433221102000000) Mar 6 10:59:27 server kernel: sd 3:0:5:0: [sdc] 3907029168 512-byte logical blocks: (2.00 TB/1.82 TiB) Mar 6 10:59:27 server kernel: sd 3:0:5:0: [sdc] 4096-byte physical blocks Mar 6 10:59:27 server kernel: sd 3:0:5:0: [sdc] Write Protect is off Mar 6 10:59:27 server kernel: sd 3:0:5:0: [sdc] Mode Sense: 7f 00 10 08 Mar 6 10:59:27 server kernel: sd 3:0:5:0: [sdc] Write cache: enabled, read cache: enabled, supports DPO and FUA Mar 6 10:59:27 server kernel: sdc: sdc1 Mar 6 10:59:27 server kernel: sd 3:0:5:0: [sdc] Attached SCSI disk Mar 6 10:59:27 server rc.diskinfo[10694]: SIGHUP received, forcing refresh of disks info. Mar 6 10:59:28 server unassigned.devices: Adding partition 'sdc1'... Mar 6 10:59:28 server unassigned.devices: Mounting partition 'sdc1' at mountpoint '/mnt/disks/backup1'... Mar 6 10:59:28 server unassigned.devices: Mount drive command: /sbin/mount -t 'xfs' -o rw,noatime,nodiratime '/dev/sdc1' '/mnt/disks/backup1' Mar 6 10:59:28 server kernel: XFS (sdc1): Mounting V5 Filesystem Mar 6 10:59:28 server kernel: XFS (sdc1): Ending clean mount Mar 6 10:59:28 server kernel: xfs filesystem being mounted at /mnt/disks/backup1 supports timestamps until 2038 (0x7fffffff) Mar 6 10:59:28 server unassigned.devices: Successfully mounted 'sdc1' on '/mnt/disks/backup1'.Nevermind. The latest update seems to have resolved the problem. I now get a BOINC Manager interface.